aeternalabshq/pullmd
Self-hosted URL-to-Markdown service with stable, refreshable share links.
10K+
aeternalabshq/pullmd repository overview
PullMD



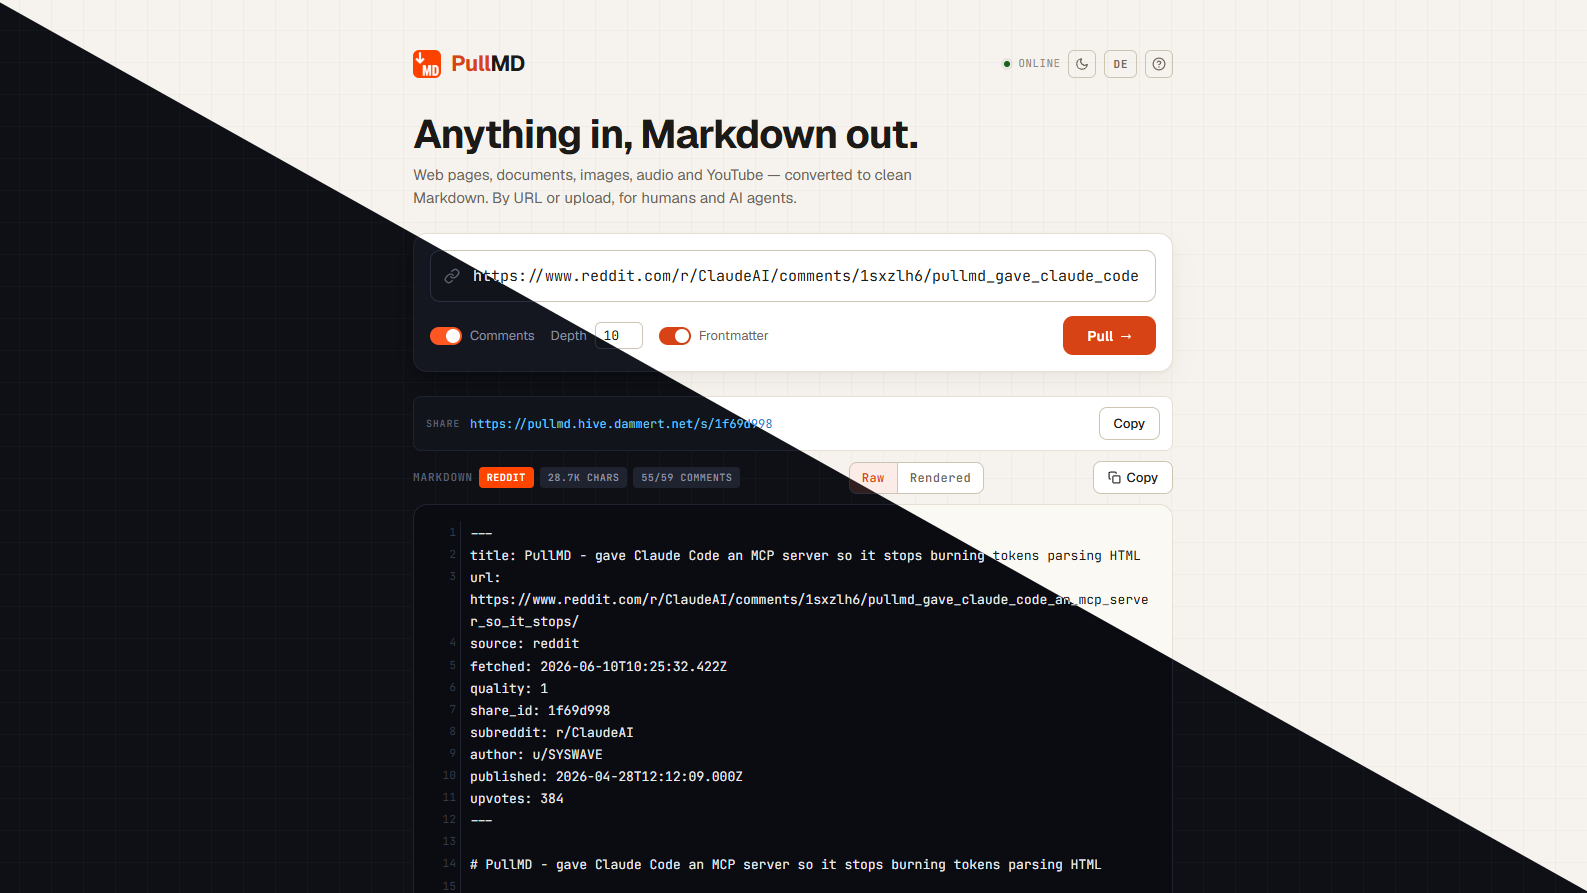
Anything in, clean Markdown out. Self-hosted conversion of web pages, documents, images, audio and YouTube videos into token-lean Markdown, for you and for your AI agents.
Documentation: aeternalabshq.github.io/pullmd, with installation, configuration, guides, the API reference and the changelog.
Quick start · Use with AI agents · Docs · API reference · Configuration · Changelog
Why PullMD
Agents are bad at reading the web. Raw HTML burns context on navigation, cookie banners and scripts, and built-in fetch tools often stumble on JavaScript-heavy pages, PDFs and comment threads. PullMD sits in between: one URL or file in, clean Markdown out, with source and metadata in YAML frontmatter instead of the body.
curl "https://pullmd.example.com/api?url=https://example.com/article"
What that saves, measured on three public pages (tokens counted with the
cl100k_base tokenizer, 2026-10-16):
| Page | Plain curl | PullMD | PullMD with ?query= |
|---|---|---|---|
| Encyclopedia article (long-form) | 99,458 | 12,549 | 662 |
| Developer documentation page | 48,611 | 6,591 | 454 |
| Reddit thread with comments, using Reddit API credentials | blocked (bot check), no thread content | 6,381 | 644 |
The curl column is what a naive fetch tool hands an agent. The last
column is query-scoped extraction: only the
sections relevant to a question.
Highlights
Reads almost anything
- Web pages through a fallback chain: Cloudflare's native Markdown, then Readability + Trafilatura (best result wins), then headless Chromium for JavaScript-heavy sites
- Reddit and Hacker News threads with their comment trees (depth and count configurable; Reddit needs API credentials)
- Documents: PDF, Word, PowerPoint, Excel, EPUB, by URL or upload, plus an optional OCR tier for table-grade PDFs
- YouTube title, description and transcript with clickable timecodes, no API key needed
- Images and audio via any OpenAI-compatible or local model (captions, transcripts)
Built for agents
- MCP server for Claude Code and other MCP clients, with OAuth 2.1 for claude.ai and Claude Desktop
- Query-scoped extraction:
?query=returns only the sections relevant to a question, typically 70-95% fewer tokens on long pages - Lean output: clean body, metadata in frontmatter, unpadded tables, configurable field allowlist
- Live share links:
/s/:idre-fetches when the cached copy is older than an hour and serves the last good snapshot if the source dies
Comfortable to self-host
- One
docker compose up, zero config, multi-arch images (amd64/arm64) on Docker Hub and GHCR - Every sidecar is optional, and PullMD degrades gracefully without it
- Auth modes from open homelab to multi-user, SSRF protection, rate limits, a health endpoint for Uptime Kuma
- Per-site extraction recipes as declarative JSON
Four ways in: PWA · REST API · MCP server · Claude Code skill
Quick start
mkdir pullmd && cd pullmd
curl -O https://raw.githubusercontent.com/AeternaLabsHQ/pullmd/main/docker-compose.yml
docker compose up -d
# -> http://localhost:3000
No .env needed: every variable has a default. Add a .env next to the
compose file to override anything. This starts PullMD and its three optional
sidecars (Trafilatura, Playwright, MarkItDown); the Playwright sidecar alone
adds about 3.7 GB of browser binaries. Images are on Docker Hub and on GHCR
(ghcr.io/aeternalabshq/pullmd, -trafilatura, -playwright, -markitdown).
More in the docs:
- Installation: compose files, running without a sidecar, running without Docker
- Reverse proxy: Traefik, nginx, Caddy,
PULLMD_TRUST_PROXY - Configuration: every environment variable
- Authentication: single-admin, multi-user, API keys, OAuth
- Upgrading and
MIGRATION.md
Use with AI agents
Once your instance runs, /help on it shows every install path with your URL
filled in. Replace ${PULLMD_URL} below with your instance's address.
MCP server (Claude Code, Cursor, other MCP clients; tools read_url, get_share, list_recent):
claude mcp add --transport http pullmd ${PULLMD_URL}/mcp
Claude Code skill:
curl -O ${PULLMD_URL}/pullmd.zip
mkdir -p ~/.claude/skills && unzip pullmd.zip -d ~/.claude/skills/
Any chat agent: paste the prompt from /help or from the docs.
Details: MCP server · claude.ai and Claude Desktop (OAuth) · Claude Code skill · Prompt for any agent · MCP tools reference
Reddit access
PullMD reads Reddit through Reddit's Data API, using REDDIT_CLIENT_ID and REDDIT_CLIENT_SECRET from an existing app. Without them Reddit blocks the requests and /api answers 502.
Reddit stopped accepting new requests for API access on 2026-10-31. It says it will start removing access for apps and users that have not registered on 2027-01-12, and close public access for all remaining apps in March 2027 (announcement). PullMD's Reddit support ends with that access. PullMD has no login or session cookie option, and none is planned.
More: Reddit and Hacker News guide.
Documentation
| Topic | Page |
|---|---|
| How the extraction pipeline works | How it works |
| REST endpoints and parameters | API reference (OpenAPI spec) |
Output, frontmatter, X-Source and status codes | Output format |
| PDF, Office, e-mail and other documents | Documents |
| Images and audio | Images and audio |
| YouTube | YouTube |
Answer only what you asked (?query=) | Query-scoped extraction |
| Share links and the cache | Share links |
| Per-site extraction rules | Site recipes and SITE-RECIPES.md |
| SSRF protection | SSRF protection and SECURITY.md |
| Health checks and stats | Monitoring |
| Something doesn't work | Troubleshooting |
AI tools can read the whole site as llms.txt. The docs live
in website/; pages are Markdown, and pull requests are welcome.
Architecture
server.js- Express app factory (createApp) with dependency injection for tests. Exposes/apiand/api/stream(SSE).lib/reddit.js- Reddit URL normalization, redirect resolution, post + comment extraction.lib/web.js- Orchestrator: Cloudflare-Markdown short-circuit, then static Readability + Trafilatura withpickBest, then optional Playwright re-render + re-extract on body-soup / low-quality output.lib/render-decision.js- Predicate that decides when to fall back to Playwright (readability-fellback + thin, body-soup signature, or quality < 0.5; plusforce/skipoverrides).lib/playwright-client.js- HTTP client for the Playwright sidecar withAbortSignalpropagation for SSE-disconnect cancellation.lib/scoring.js- Quality scoring used to pick between extractors and as a render-trigger heuristic.lib/cache.js- SQLite cache (better-sqlite3) with configurable retention (default 90 days) and 32-hex (128-bit) share ids.lib/mcp.js- Stateless MCP server registering the three tools.lib/distrib.js- Public-URL substitution in/helpand/pullmd.zip.trafilatura-sidecar/- Python sidecar (FastAPI) wrapping Trafilatura.playwright-sidecar/- Python sidecar (FastAPI + Playwright + Chromium) for JS-rendered pages.markitdown-sidecar/- Python sidecar (FastAPI) wrapping MarkItDown for document conversion (PDF, Office, EPUB, …) plus the keyless/youtubetranscript endpoint.lib/markitdown-client.js- HTTP client for the markitdown sidecar (documents + YouTube).lib/youtube.js- YouTube URL detection and normalization.lib/llm/- provider resolver + adapters for image captioning (vision), audio transcription (STT), and PDF OCR against OpenAI-compatible endpoints.lib/frontmatter.js- YAML frontmatter builder with thePULLMD_FRONTMATTER_FIELDSallowlist.lib/coverage-guard.js- detects extractions that kept only a sliver of the page and recovers the container holding the body.lib/article-series.js- detects pages that split one piece of writing across several<article>blocks by the same author and joins them.lib/query-extract.js- Opt-in query-scoped extraction (?query=): BM25 over heading-based sections of the converted markdown, returning only the relevant sections/blocks. Composeslib/markdown-sections.js(block/section parser) andlib/bm25.js(tokenizer + scorer).public/- PWA frontend (vanilla JS, dark/paper themes, service worker, EventSource client for/api/stream).skill/pullmd/- Claude Code skill source (templated with__PULLMD_URL__).
License
GNU AGPL v3 - Copyright © 2026 Aeterna Labs.
PullMD is free software: you can redistribute it and modify it under the terms of the GNU Affero General Public License as published by the Free Software Foundation, version 3 or later. If you run a modified version as a network service, you must make your modifications available to its users.
Tag summary
Content type
Image
Digest
sha256:741a3a571…
Size
99 MB
Last updated
3 days ago
docker pull aeternalabshq/pullmd