annashcherbina/dragonn
Dockerfile for Dragonn: http://kundajelab.github.io/dragonn/
166
annashcherbina/dragonn repository overview
DragoNN


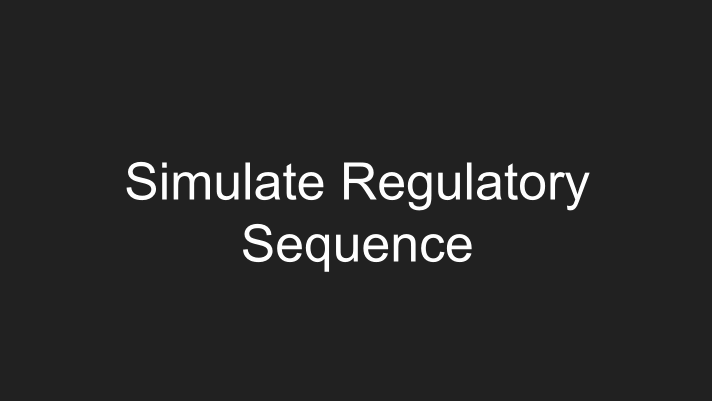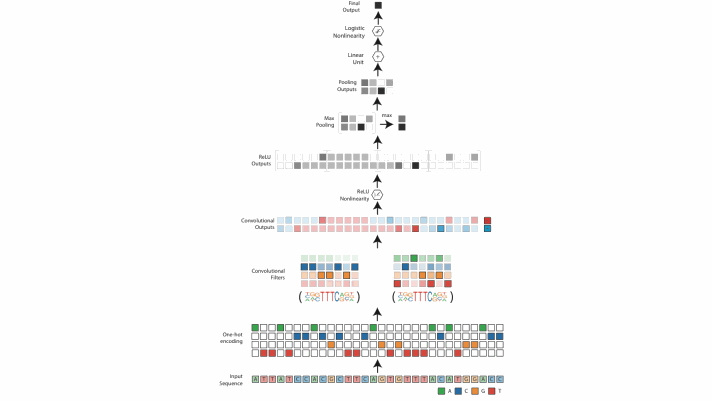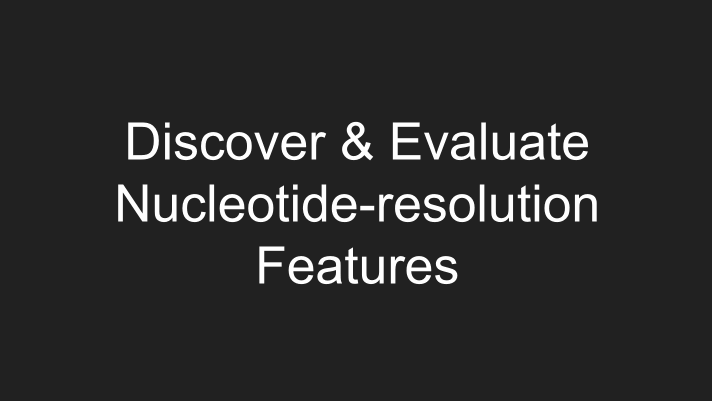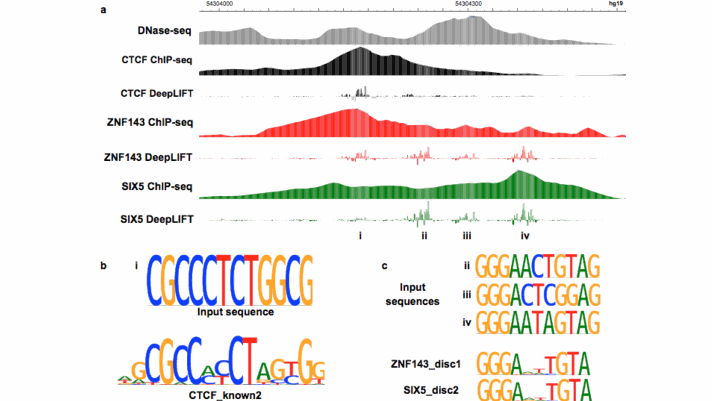
The dragonn package implements Deep RegulAtory GenOmic Neural Networks (DragoNNs) for predictive modeling of regulatory genomics, nucleotide-resolution feature discovery, and simulations for systematic development and benchmarking.
Installation
To install the latest released version of DragoNN, install the Anaconda python distribution. Then, run:
conda install dragonn -c kundajelab
DragoNN is compatible with Python2 and Python3. Specific optional features such as DeepLIFT and MOE are compatible with Python2 only.
15 seconds to your first DragoNN model
The dragonn package provides a simple command line interface to train DragoNN models, test them, and predict on sequence data. Train an example model by running:
dragonn train --pos-sequences examples/example_pos_sequences.fa --neg-sequences examples/example_neg_sequences.fa --prefix training_example
This will store a model file, training_example.model.json, with the model architecture and a weights file, training_example.weights.h5, with the parameters of the trained model. Test the model by running:
dragonn test --pos-sequences examples/example_pos_sequences.fa --neg-sequences examples/example_neg_sequences.fa --arch-file training_example.arch.json --weights-file training_example.weights.h5
This will print the model's test performance metrics. Model predictions on sequence data can be obtained by running:
dragonn predict --sequences examples/example_pos_sequences.fa --arch-file training_example.arch.json --weights-file training_example.weights.h5 --output-file example_predictions.txt
This will store the model predictions for sequences in example_pos_sequences.fa in the output file example_predictions.txt. Interpret sequence data with a dragonn model by running:
dragonn interpret --sequences examples/example_pos_sequences.fa --arch-file training_example.arch.json --weights-file training_example.weights.h5 --prefix example_interpretation
This will write the most important subsequence in each input sequence along with its location in the input sequence in the file example_interpretation.task_0.important_sequences.txt. Note: by default, only examples with predicted positive class probability >0.5 are interpreted. Examples below this threshold yield important subsequence of Ns with location -1. This default can be changed with the flag --pos-threshold.
We encourage DragoNN users to share models in the Kipoi Genomics Model Zoo. Enjoy!
DragoNN paper supplement
We provide trained models, data, and code in the paper supplement to reproduce results in the DragoNN manuscript.
Tag summary
Content type
Image
Digest
Size
2.2 GB
Last updated
almost 8 years ago
docker pull annashcherbina/dragonn:keras_2.2_tensorflow_1.6_purekeras