
hangrylabs/sidon
Local voice restoration, two-speaker separation, and audio conversion with a web UI and API.
1.6K
hangrylabs/sidon repository overview
Development version v1.0.0-snapshot, targeting the first v1.0.0 release.
Local voice restoration and two-speaker separation, with a browser studio and audio-job API in one container.
🎧 Hear the before-and-after comparison · Project website and documentation
Listen to three VoxCPMTTS samples before and after Sidon restoration, using the same spoken text: “Give your voice a cleaner finish with Sidon, local audio restoration that helps rough recordings sound their best.”
- Enhance: restore noisy or degraded single-speaker speech at 48 kHz.
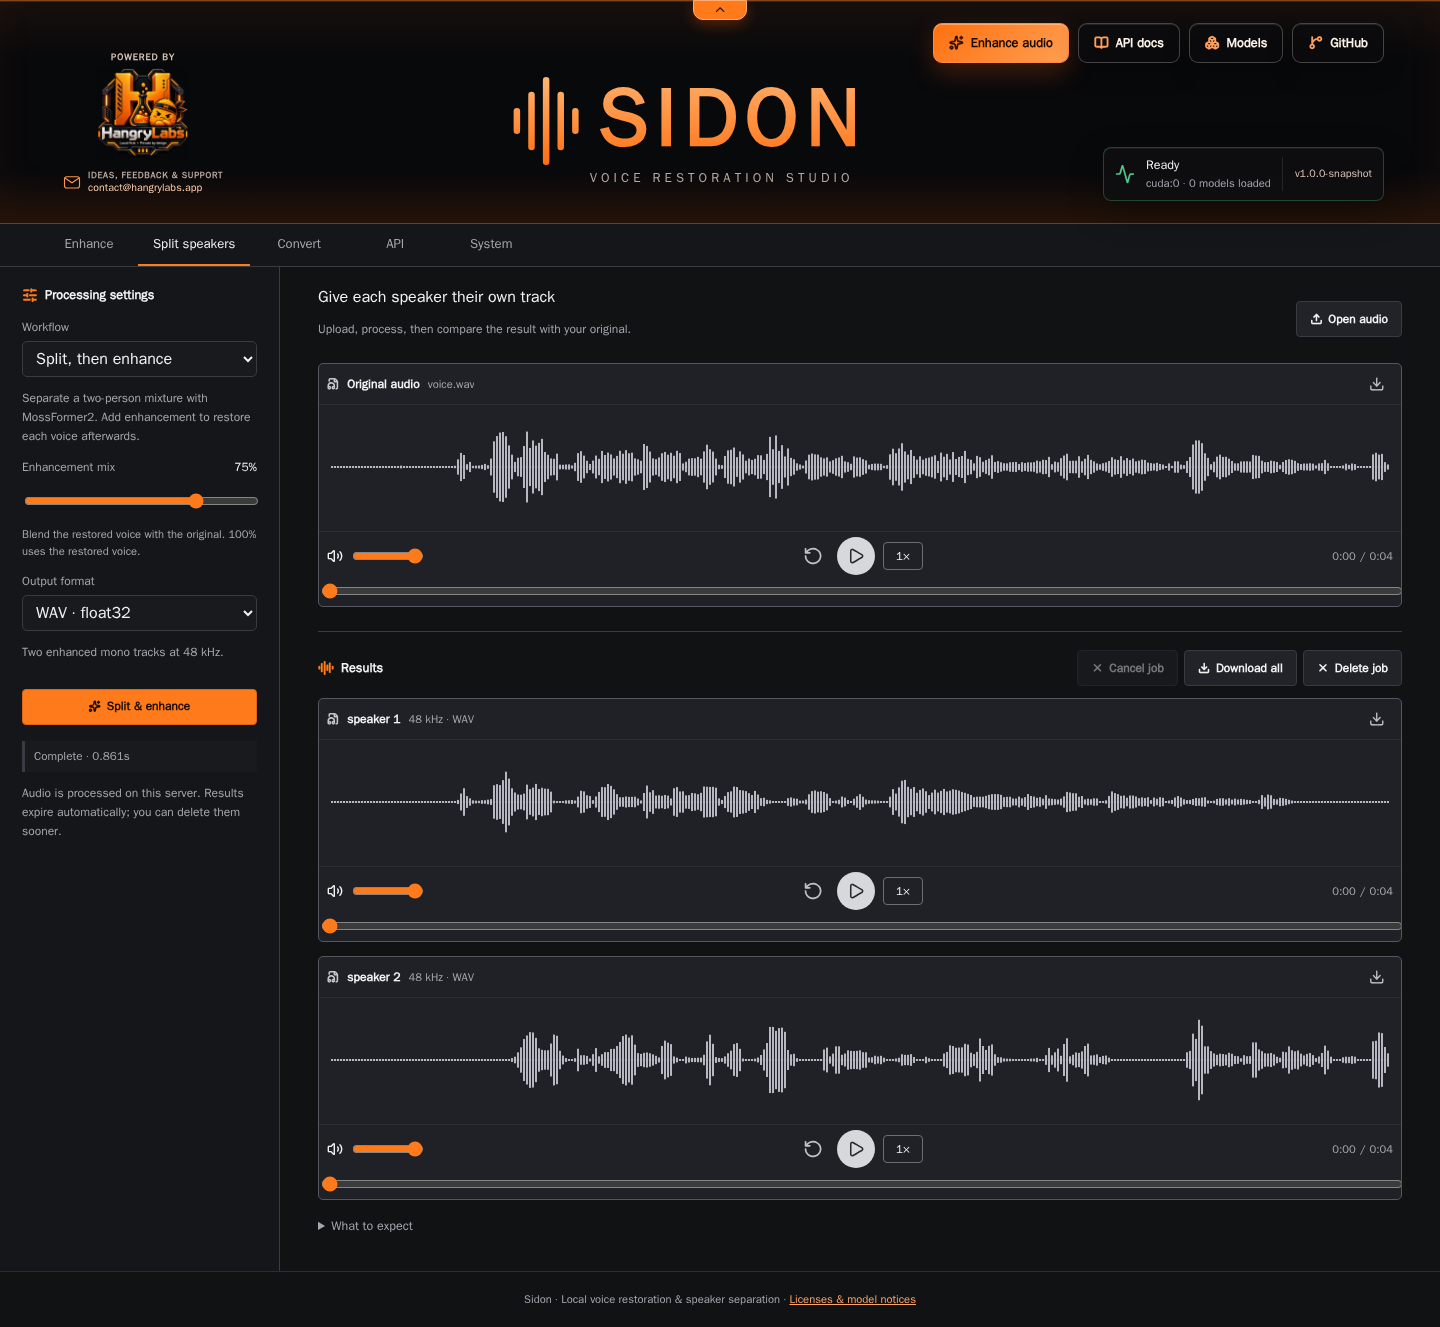
- Split: get two 16 kHz speaker tracks with MossFormer2.
- Split, then enhance: restore both separated tracks at 48 kHz.
- Convert: change formats without loading an inference model; preserve channels (MP3 supports up to two).
- Upload WAV, FLAC, Opus, MP3, AAC/M4A, OGG, AIFF or WebM audio. Download float WAV, 24-bit FLAC, Opus, MP3, AAC/M4A or Ogg Vorbis, individually or in a ZIP.
- System controls model residency, persisted defaults and live GPU telemetry.
- Supported CUDA hosts automatically use the optimized F32 restoration path, with a fused vocoder activation and a folded encoder for longer windows. The first model load builds a small local kernel; the volume retains its cache.
Quick start
The publication workflow targets hangrylabs/sidon and ghcr.io/hangry-labs/sidon. The following registry commands apply after the first successful image publication; build from source until then.
docker run -d --name sidon --gpus all -p 127.0.0.1:7868:7868 -v sidon_data:/app/persistent hangrylabs/sidon:latest
Open http://localhost:7868. Linux x86-64, Python 3.13, PyTorch 2.14 / CUDA 13.0. Full images bake all pinned CPU/CUDA weights and work offline. NVIDIA use needs a CUDA 13-compatible host driver and container support. For CPU, omit --gpus all and add -e SIDON_DEVICE=cpu.
Tiny image
docker run -d --name sidon-tiny --gpus all -p 127.0.0.1:7868:7868 -v sidon_data:/app/persistent hangrylabs/sidon:latest_tiny
Same UI/API, no baked weights. First use downloads only needed assets; keep the volume. CPU and CUDA restoration exports differ. After downloading all needed variants, restart with the same volume and HF_HUB_OFFLINE=1 for cached use.
Tags and sources
Main builds publish latest, latest_tiny, latest_sources. Stable Git tags publish vX.Y or vX.Y.Z and matching _tiny / _sources variants. Stable tags are immutable. Published application images identify their exact corresponding-source image in the app.hangrylabs.sources label; source images contain /sources and need no executable runtime.
API
Versioned audio-processing routes use OpenAI-style model, response_format,
bearer authentication, model discovery and structured errors. They are native
Sidon extensions, not OpenAI speech endpoints. No streaming is implemented.
curl http://localhost:7868/v1/models
curl -X POST http://localhost:7868/v1/audio/enhancements -F [email protected] -F response_format=opus --output restored.opus
curl -X POST http://localhost:7868/v1/audio/conversions -F [email protected] -F response_format=flac --output converted.flac
Use /v1/audio/separations for two-track ZIP output; add enhance=true to restore
both speakers. Add response_mode=job for HTTP 202, then poll
/v1/audio/jobs/JOB_ID or cancel through POST /v1/audio/jobs/JOB_ID/cancel.
The API guide covers the full
contract. The existing Studio API also remains supported:
curl -X POST http://localhost:7868/api/jobs -F [email protected] -F mode=enhance -F strength=1 -F output_format=wav
curl http://localhost:7868/api/jobs/JOB_ID
curl -OJ http://localhost:7868/api/jobs/JOB_ID/files/results.zip
Submission returns HTTP 202 and a job ID. Wait for status=done before downloading. Modes: enhance, separate, separate_enhance, convert. Set output_format to wav, flac, opus, mp3, m4a, aac, or ogg. Full schema: /openapi.json; examples are also in the UI's API tab.
Conversion-only WAV/FLAC retains sample rate/channels. Compressed exports use 48 kHz: Opus 96 kbps VBR, MP3/AAC 192 kbps, Ogg Vorbis quality 5. Enhancement and separation remain mono. FFmpeg and its matching sources/notices are included.
Configuration and privacy
Persist /app/persistent. Defaults: 100 MB/file, 600 seconds/file, four active jobs, one inference worker, 24-hour audio/result retention. Change with SIDON_MAX_UPLOAD_MB, SIDON_MAX_AUDIO_SECONDS, SIDON_RETENTION_HOURS. SIDON_DEVICE=auto chooses CUDA when available, otherwise CPU.
Set SIDON_API_KEY before exposing the service; clients send Authorization: Bearer YOUR_KEY. All clients share one instance's jobs/settings. Use separate instances for tenant isolation, and a TLS/authenticated reverse proxy for remote hosting.
Both /api/* and /v1/* share a bounded queue: four active slots by default,
including upload parsing and validation, with one processing worker. Configure
SIDON_MAX_ACTIVE_JOBS from 1 to 64. Ready jobs run FIFO; saturation returns 429
with Retry-After: 1. Pending cancellation frees capacity immediately; running
cancellation is cooperative. /v1/audio/queue and job status expose queue position
and wait/processing/total timings. One OS-locked owner per data directory prevents
accidental multi-worker corruption; use one instance per GPU allocation.
Audio stays on your server until deletion or expiry. Tiny images download from Hugging Face; full images need no model downloads. Restoration can alter voice character and add artifacts; compare results. Separation always returns two tracks, and ambiguous overlaps may swap labels.
Attribution and licenses
Sidon restoration: sarulab-speech, publisher-declared MIT weights. Separation: MossFormer2 / ClearerVoice-Studio, publisher-declared Apache-2.0 weights. Source contributions use Apache-2.0 with retained MIT material. The UI/packaging conventions credit Hangry Labs faster-qwen3-tts-studio; icon notices credit Lucide.
Container dependencies keep their own licenses, including LGPL/GPL components and NVIDIA terms. Matching source images and collected notices accompany publication. Model grants do not establish rights to every training datum or uploaded recording.
Source, documentation and local builds · Licensing · Contact Hangry Labs
Tag summary
Content type
Image
Digest
sha256:d3f800b03…
Size
5.5 GB
Last updated
20 days ago
docker pull hangrylabs/sidon