irvlutd/rpx
RPX model runtimes for image/video depth, tracking, camera pose, and VQA.
2.7K
irvlutd/rpx repository overview
RPX model environments
Ready-to-run Docker images for every model evaluated in Same Scene, Different Story: Evaluating Robot Perception Across Scene Phases in the Wild, a real-world benchmark that scores robot perception on the same scenes before, during and after manipulation.
Dataset · Toolkit docs · PyPI · GitHub · All tags
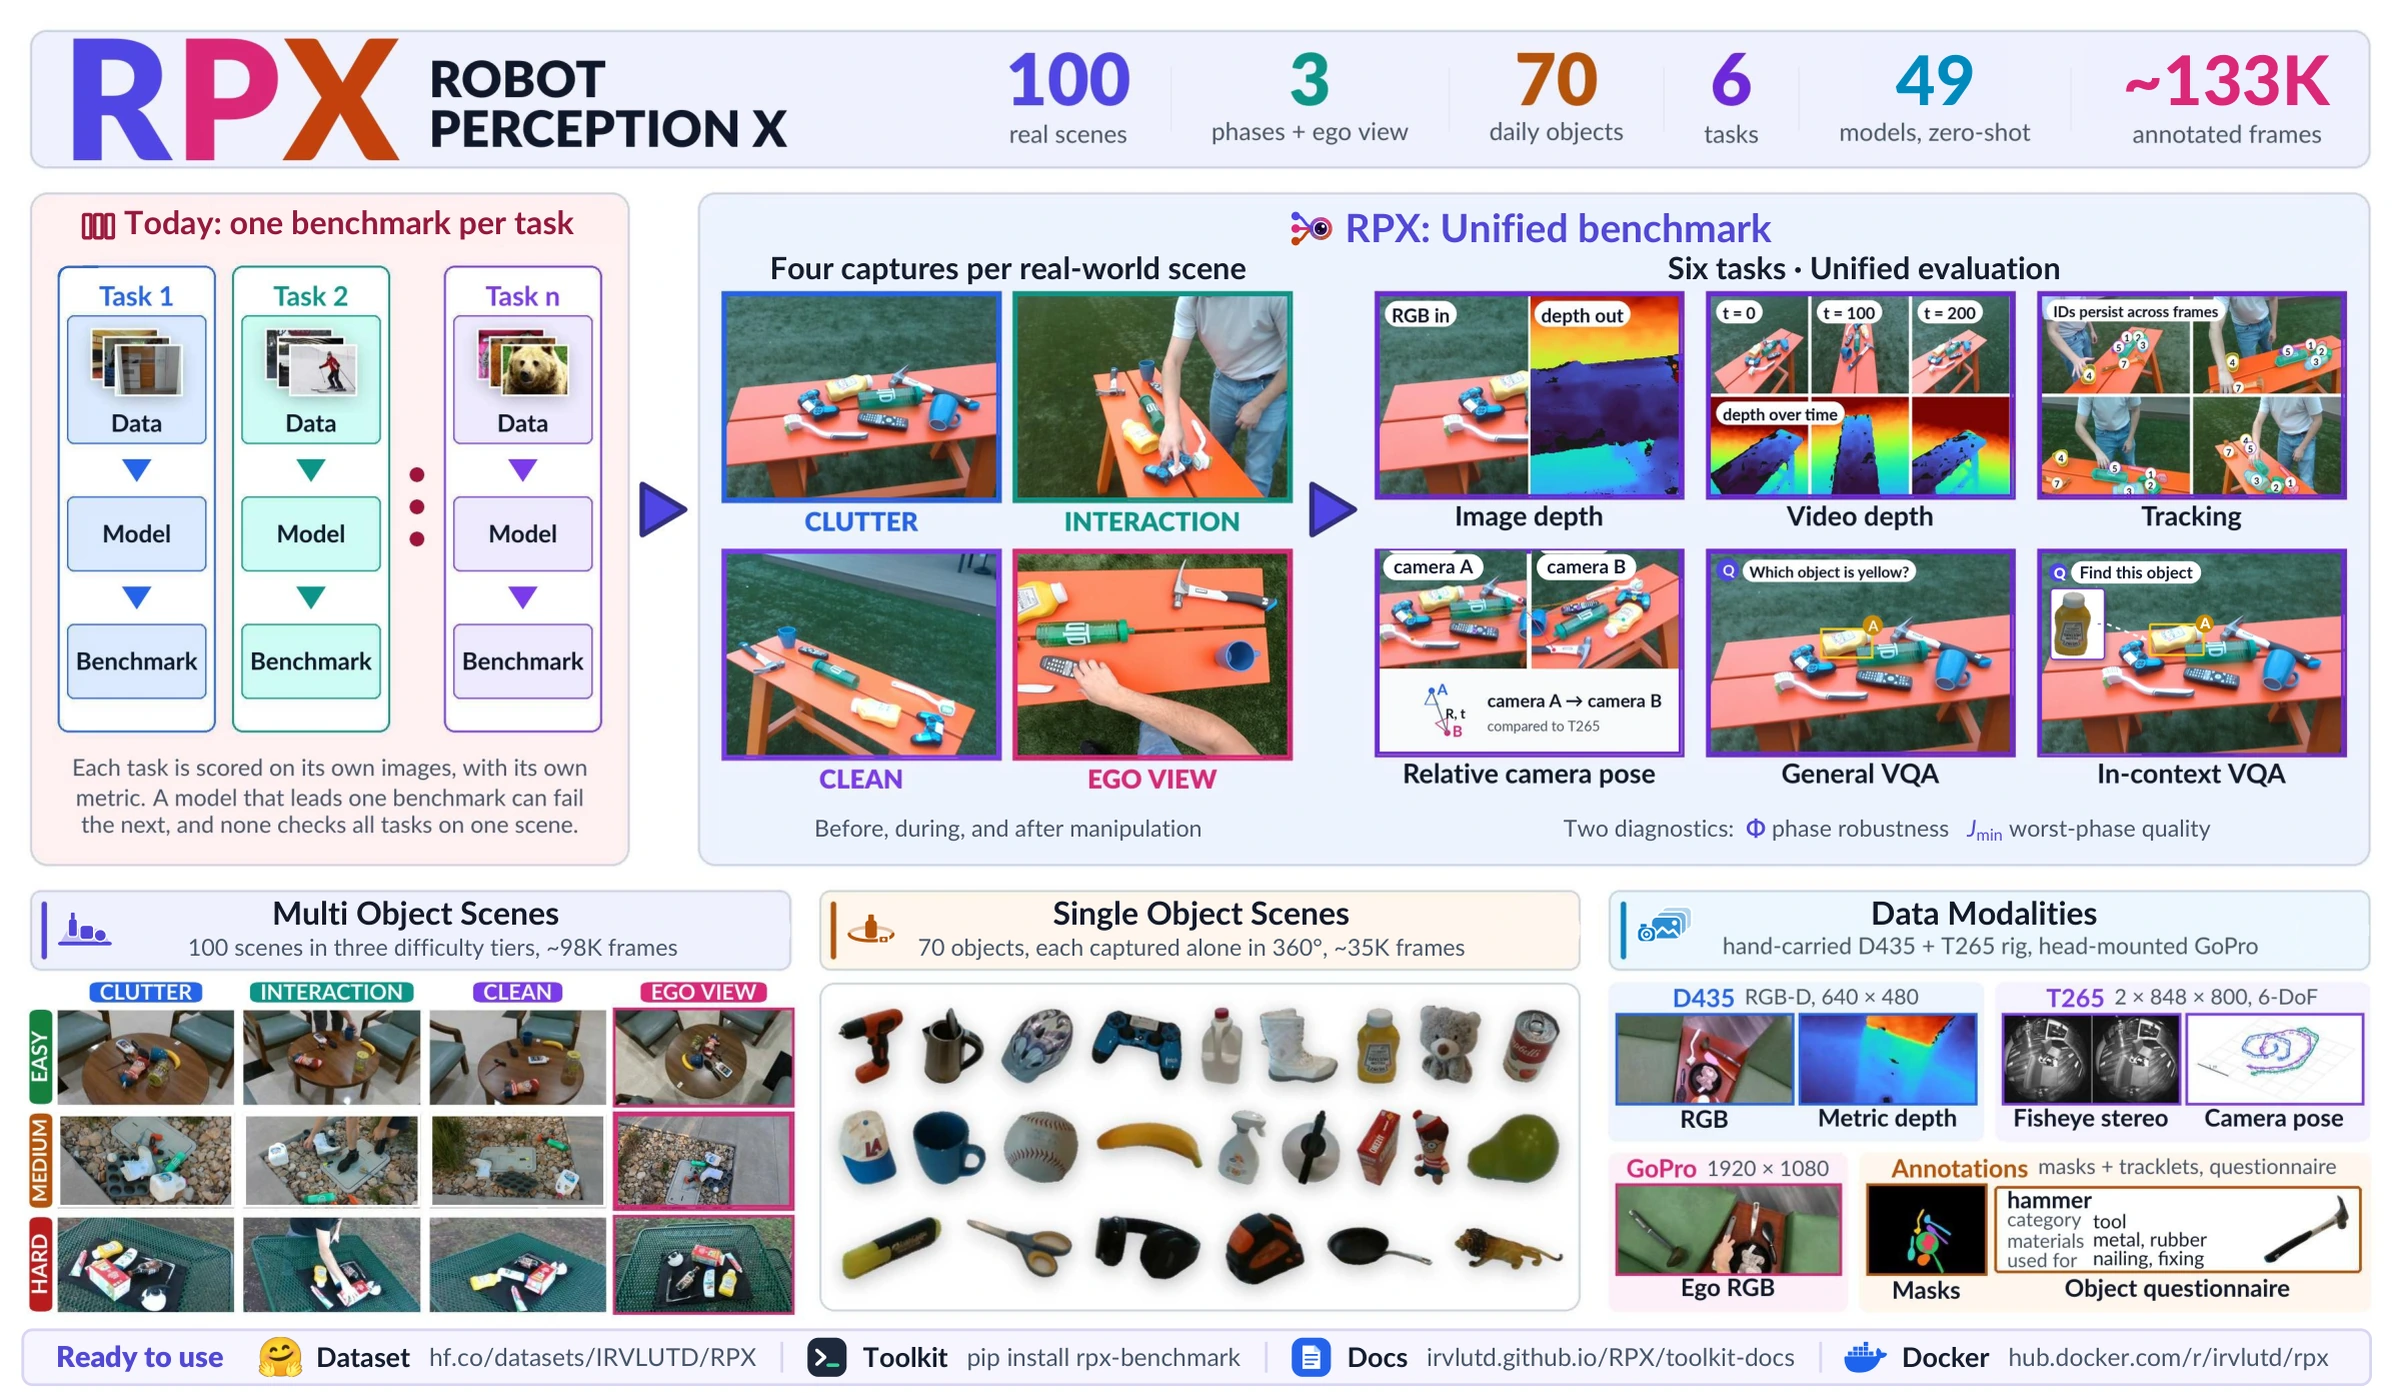
| 49 | 6 | 100 | linux/amd64 |
|---|---|---|---|
| models from the paper | perception tasks | real scenes | NVIDIA GPU |
Pick an image · Quick start · Reproducibility · Results · Citation
Pick an image
Each task's image is built cumulatively, so one tag holds every model the paper evaluated on that task.
Always name a tag. A bare
docker pull irvlutd/rpxfetches an old, unrelated capture environment, and tags not listed here are earlier build stages kept for provenance.
T1 Image depth · 10 models
docker pull irvlutd/rpx:depth-zipdepth-latest
DA-V2 Large, DA3 Metric-L, Depth Pro, FE2E, HyDen, Lotus-2, Metric3D V2, MoGe-2 ViT-L, UniDepth V2, ZipDepth
T2 Video depth · 8 models, plus DVD
docker pull irvlutd/rpx:depth-zipdepth-latest
docker pull irvlutd/rpx:depth-dvd-latest      # DVD v1.1
ChronoDepth, DA3 (video), DepthCrafter, MonST3R, RollingDepth, VGGT, ViGeo, Video-DA. GemDepth has a build recipe but no published image.
T3 Object tracking · 8 models, plus prompted trackers
docker pull irvlutd/rpx:tracking-dam4sam-rpx-latest              # first-frame mask
docker pull irvlutd/rpx:tracking-sam3.1-bbox-rpx-latest          # box prompt
docker pull irvlutd/rpx:tracking-sam3.1-text-rpx-latest          # text prompt
docker pull irvlutd/rpx:tracking-grounded-sam2-text-rpx-latest   # text prompt
SAM 2, EdgeTAM, Cutie, SAM2Long, SAM 2++, MiTS, XMem, DAM4SAM in the first image; SAM 3.1 and Grounded SAM 2 in the prompted ones.
T4 Relative camera pose · 10 models
docker pull irvlutd/rpx:rcpe-monst3r-rpx-latest
VGGT, DA3, CUT3R, DUSt3R, MASt3R, MUSt3R, Reloc3R, Pi3X, Fast3R, MonST3R. DA3, MonST3R and VGGT are also in the depth image; use this one for camera pose.
T5 VQA and T6 In-context VQA · 12 configurations
docker pull irvlutd/rpx:vqa-vllm
Cosmos Reason2, DeepSeek-VL2, Florence-2, InternVL 3.5, PaliGemma 2 and Qwen3-VL.
Quick start
You need Linux x86-64, an NVIDIA GPU with the NVIDIA Container Toolkit, and disk space for the image, checkpoints and dataset cache. Weights and data download at run time.
# See what the image can run
docker run --rm irvlutd/rpx:vqa-vllm list-models

# Check the environment and GPU
docker run --rm --gpus all irvlutd/rpx:vqa-vllm verify
verify checks the runtime, not a model. Mount caches and results from the host so they outlive the container:
mkdir -p "$HOME/.cache/huggingface" "$HOME/.cache/rpx-vqa" "$PWD/rpx-results"
docker run --rm --gpus all --ipc=host -e HF_TOKEN \
  -v "$HOME/.cache/huggingface:/cache/huggingface" \
  -v "$HOME/.cache/rpx-vqa:/cache/rpx-vqa" \
  -v "$PWD/rpx-results:/outputs" \
  irvlutd/rpx:vqa-vllm help
HF_TOKEN is only needed for gated checkpoints. Each task's guide then walks through a one-model smoke run and the full benchmark:
| Task | Guide |
|---|---|
| T1, T2 | Image and video depth, DVD |
| T3 | Object tracking |
| T4 | Relative camera pose |
| T5, T6 | VQA and in-context VQA |
To score your own model you don't need Docker: pip install rpx-benchmark and follow the toolkit docs.
Reproducibility
-latest tags move. For results you plan to report, pin the image by digest and record it with the checkpoint revision, dataset revision and model arguments:
docker image inspect irvlutd/rpx:tracking-dam4sam-rpx-latest \
  --format '{{index .RepoDigests 0}}'
# irvlutd/rpx@sha256:...  (use this reference for every later run)
Results
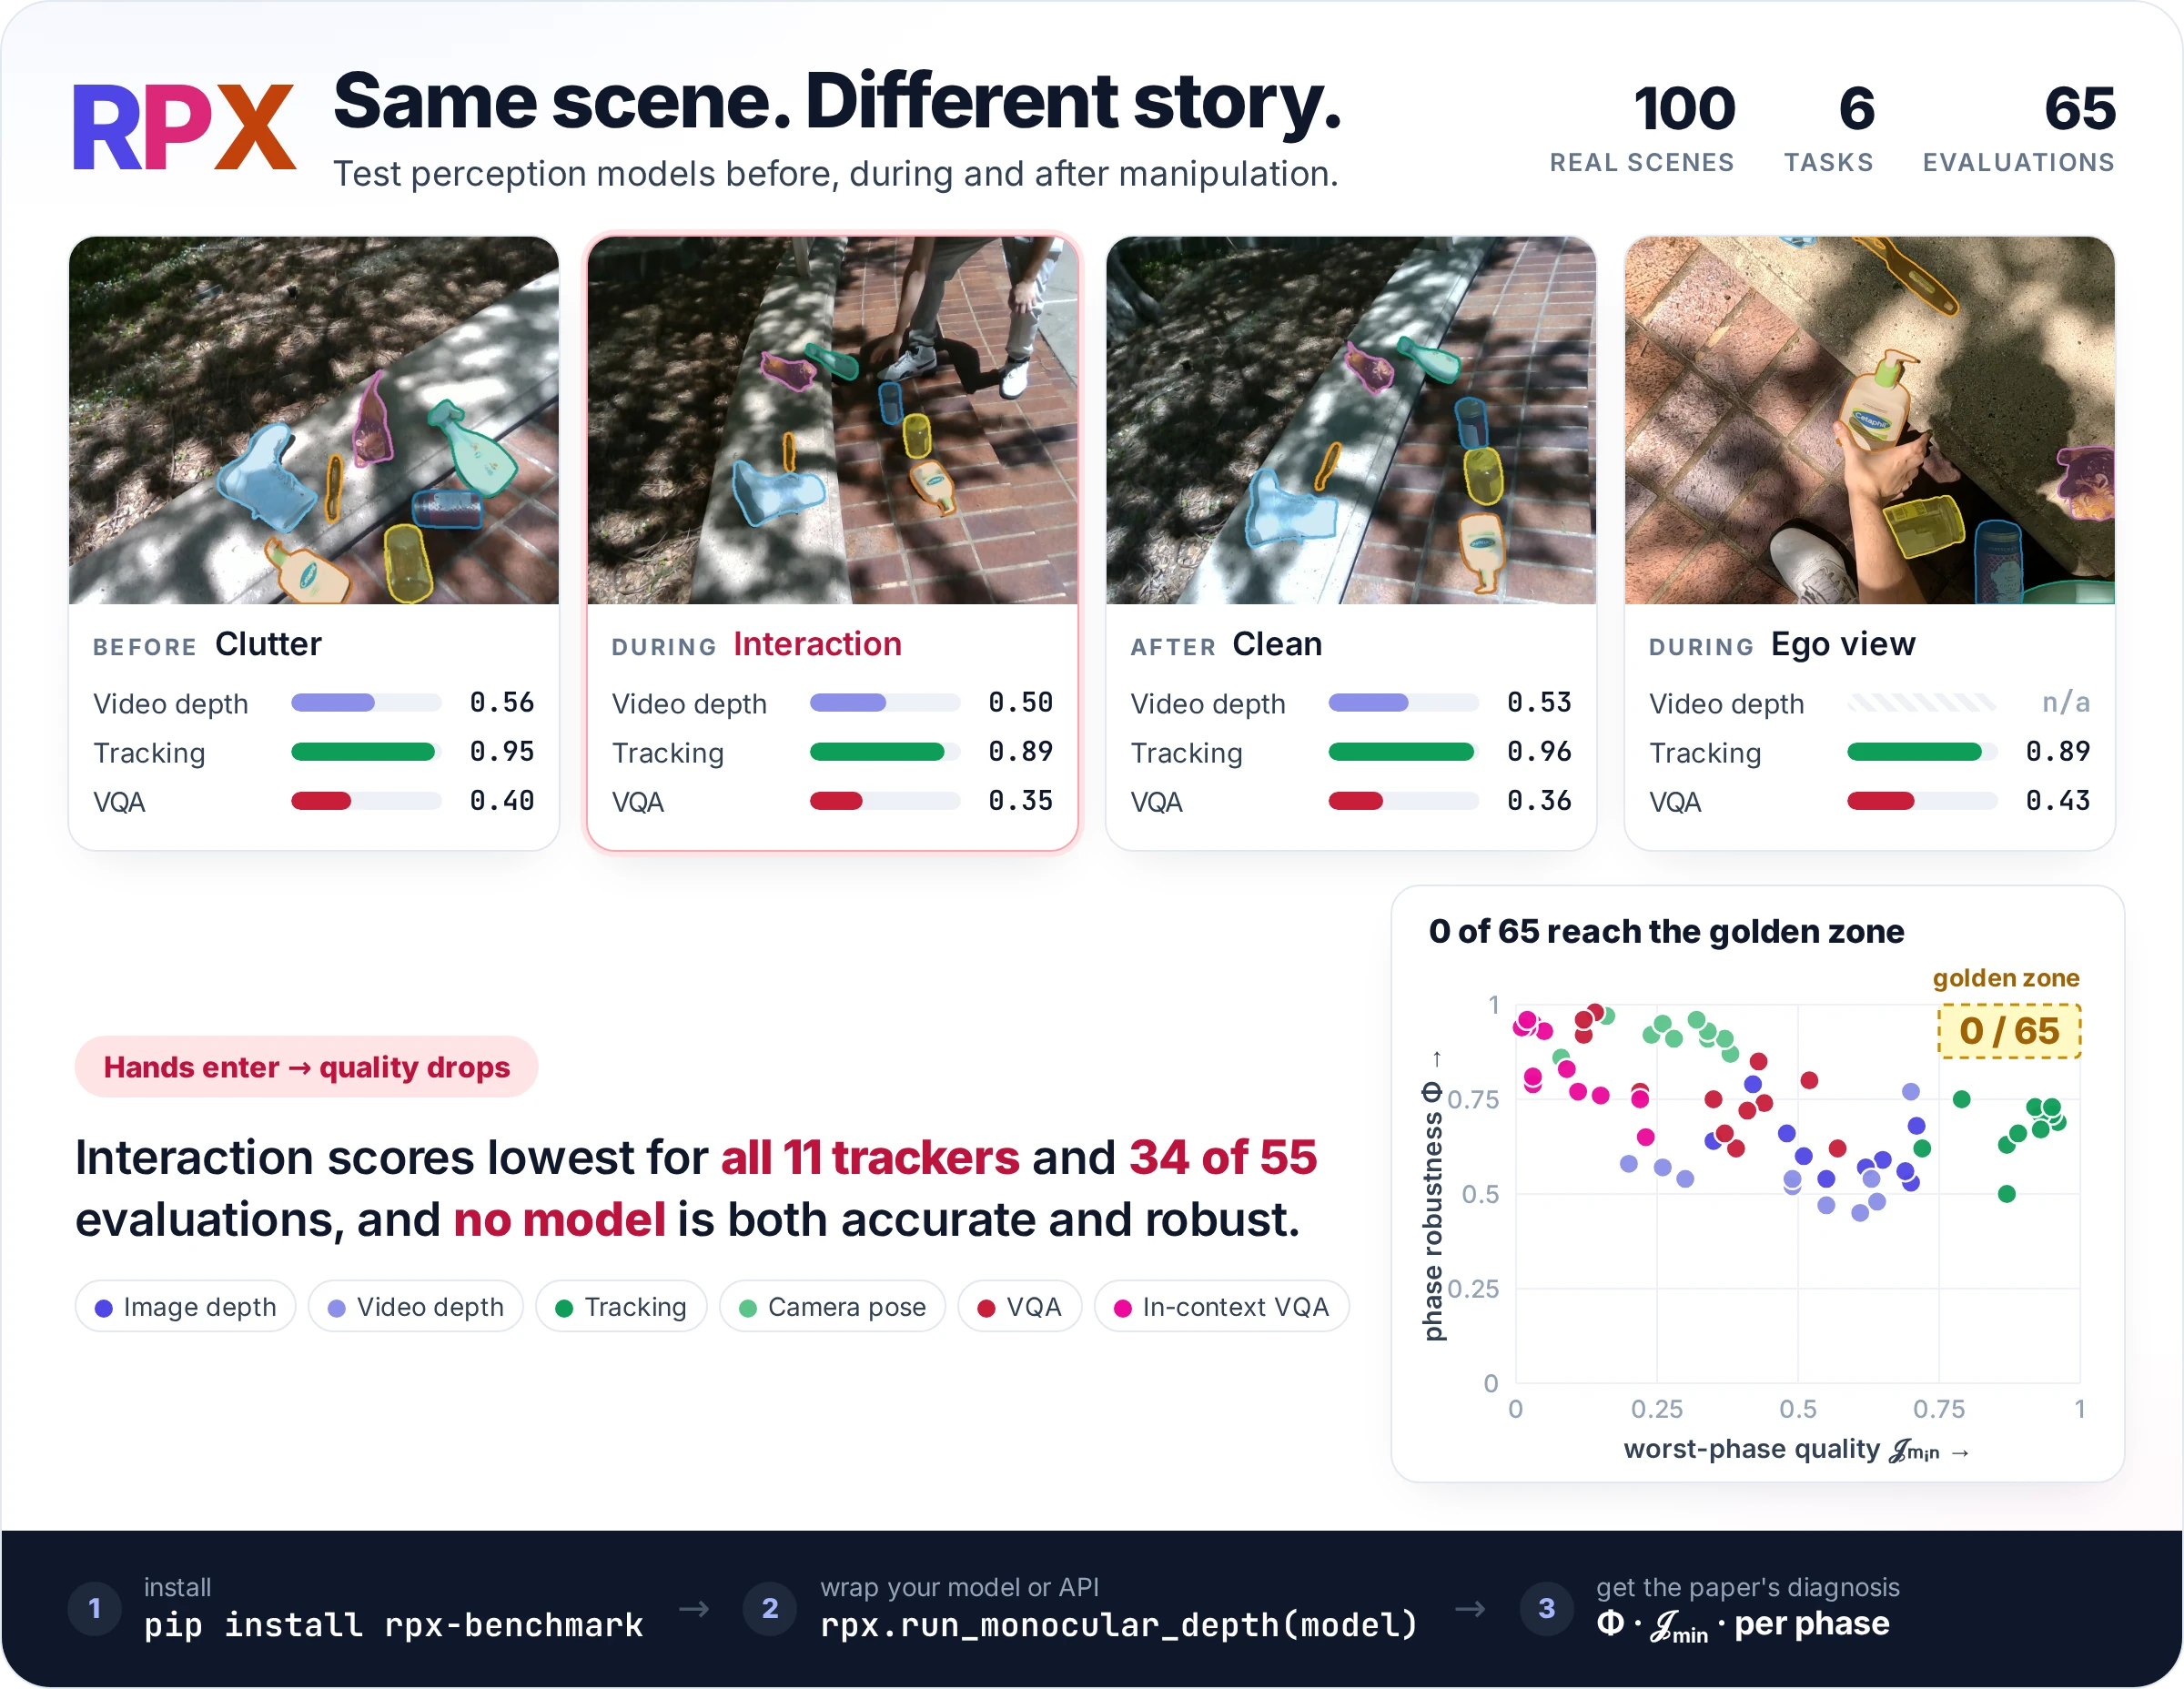
Quality drops once hands enter the scene, and none of the paper's 65 evaluations is both accurate and robust across phases.
Citation
@misc{rpx2026,
  title  = {Same Scene, Different Story: Evaluating Robot Perception
            Across Scene Phases in the Wild},
  author = {{Jishnu Jaykumar P} and Kadosh, Itay and Vijayakumar, Narendhiran
            and Kamath, Srinanditha and Allu, Sai Haneesh and Rangappa, Govind Tyagi
            and Maheshwari, Animesh and Wang, Jikai and Xiang, Yu},
  year   = {2026},
  note   = {Dataset: \url{https://huggingface.co/datasets/IRVLUTD/RPX}}
}
Environment code is MIT-licensed. Each model keeps its own license. Built at the Intelligent Robotics and Vision Lab, The University of Texas at Dallas.
Tag summary
Content type
Image
Digest
sha256:424aecd70…
Size
10.2 GB
Last updated
23 days ago
docker pull irvlutd/rpx:vqa-vllm-sha-ee4070b0726b