malkaf/vllm-blackwell-optimizer
vLLM for Blackwell (SM_120) & Kernel 6.14. for RTX 5090. 59 t/s on DeepSeek-R1 via FlashInfer
10K+
malkaf/vllm-blackwell-optimizer repository overview
vLLM Optimized Stack: NVIDIA Blackwell (SM_120) & Kernel 6.14 🚀
Official Docker Image for high-performance LLM inference on RTX 5090. This image provides a source-compiled vLLM environment specifically tuned for the SM_120 architecture and the Linux Kernel 6.14+ stack.
| Metric | Performance |
|---|---|
| Throughput | 59.0 tokens/s (DeepSeek-R1-32B-AWQ) |
| Architecture | Native SM_120 (Blackwell) |
| Stability | FlashInfer Backend (No Flash-Attn symbol errors) |
| Kernel Support | Linux 6.14 native DMA-BUF |
⚡ Quick Start (Pull & Run)
If you have your hardware ready, you can pull and run the pre-optimized image:
# 1. Pull the image
docker pull malkaf/vllm-blackwell-optimizer:latest

# 2. Deploy using Docker Compose (Recommended)
docker compose up -d
🛠️ Infrastructure Configuration (.env)
The behavior of this image is controlled via environment variables. Create a .env file to map your local hardware and tokens:
# --- INFRASTRUCTURE SETTINGS ---
# Mandatory: Your Hugging Face Token
HF_TOKEN=your_token_here

# Hardware: Target architecture for Blackwell
VLLM_GPU_ARCH=12.0

# Performance: Compilation threads (e.g., 42 for Threadripper 7960X)
MAX_JOBS=42

# --- KERNEL 6.14 OPTIMIZATIONS ---
# Force native kernel memory handling (DMA-BUF)
NCCL_DMABUF_ENABLE=1

# P2P Level (PCI is required for early Blackwell drivers)
NCCL_P2P_LEVEL=PCI
VLLM_SKIP_P2P_CHECK=1
🧠 Why this Image? (The Blackwell Bridge)
Standard vLLM images fail on RTX 5090 / Kernel 6.14 setups. This image implements the following architectural fixes:
- Flash-Attention Bypass: Standard
flash-attntriggersundefined symbolerrors on SM_120. We have pivoted the entire engine to FlashInfer, ensuring stable attention kernels. - DMA-BUF Integration: Replaces the unstable
nvidia_peermemmodule with native Kernel 6.14 DMA-BUF support (NCCL_DMABUF_ENABLE=1), preventing 60-second deadlocks. - AWQ Stability: Fixed "garbage character" output by using native 4-bit AWQ kernels, the only stable quantization path for early Blackwell silicon.
📊 Performance Benchmark
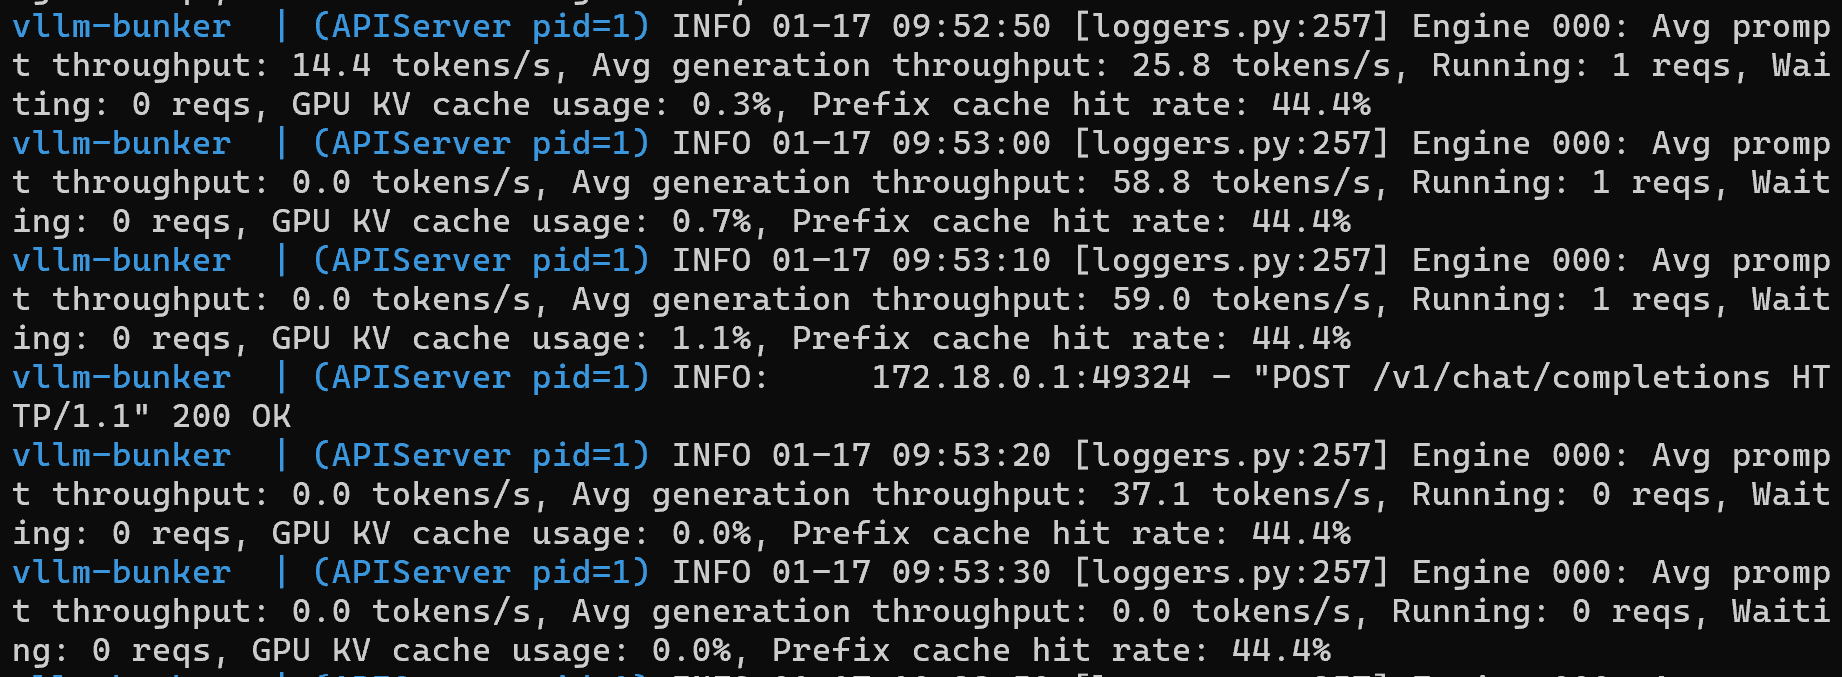 DeepSeek-R1-32B achieving 59.0 tokens/s on dual RTX 5090.
📂 Volume Mapping
To avoid re-downloading weights, map your local model cache:
volumes:
  - "/your/local/models:/model_dir"
  - "/your/huggingface/cache:/root/.cache/huggingface"
🖥️ Hardware Prerequisites
- GPU: NVIDIA RTX 5090 (SM_120).
- Driver: NVIDIA 590.48 or higher.
- Kernel: Linux Kernel 6.14+ (Recommended for native DMA-BUF).
- Toolkit: NVIDIA Container Toolkit installed and configured.
🤝 Project & Support
This image is part of the Blackwell Linux Infra Optimizer project.
- Source Code: GitHub Repository
- Maintainer: informatico-madrid
If this stack stabilizes your Blackwell production, please give us a star on GitHub! ⭐
Tag summary
Content type
Image
Digest
sha256:8741942e1…
Size
20.5 GB
Last updated
9 months ago
docker pull malkaf/vllm-blackwell-optimizer