overheatsystem/kallia
Semantic Document Processing Library
281
overheatsystem/kallia repository overview
Kallia


Kallia is a semantic document processing library that converts documents into intelligent semantic chunks. The library specializes in extracting meaningful content segments from documents while preserving context and semantic relationships.
🚀 Features
- Document-to-Markdown Conversion: Standardized processing pipeline for various document formats
- Semantic Chunking: Intelligent content segmentation that respects document structure and meaning
- PDF Support: Robust PDF processing with extensible architecture for additional formats
- RESTful API: FastAPI-based service with comprehensive error handling
- Interactive Playground: Chainlit-powered chat interface for document Q&A
- Memory Management: Long-term and short-term memory systems for conversational context
- Configurable Processing: Adjustable parameters (temperature, token limits, page selection)
- Docker Support: Containerized deployment for both core API and playground
📋 Requirements
- Python 3.11 or higher
- FastAPI 0.115.14
- Docling 2.41.0
🛠️ Installation
Using pip
pip install kallia
From Source
git clone https://github.com/kallia-project/kallia.git
cd kallia
pip install -e .
🏗️ Project Structure
kallia/
├── kallia/
│   ├── core/                    # Core API service
│   │   ├── kallia_core/         # Main library modules
│   │   │   ├── main.py          # FastAPI application
│   │   │   ├── documents.py     # Document processing
│   │   │   ├── chunker.py       # Semantic chunking
│   │   │   ├── memories.py      # Memory management
│   │   │   ├── models.py        # Data models
│   │   │   └── ...
│   │   ├── requirements.txt     # Core dependencies
│   │   ├── Dockerfile          # Core service container
│   │   └── docker-compose.yml  # Core service orchestration
│   └── playground/             # Interactive chat interface
│       ├── kallia_playground/  # Playground modules
│       │   ├── main.py         # Chainlit application
│       │   ├── qa.py           # Q&A functionality
│       │   └── ...
│       ├── requirements.txt    # Playground dependencies
│       ├── Dockerfile         # Playground container
│       └── docker-compose.yml # Playground orchestration
├── tests/                     # Test suite
├── assets/                    # Sample documents
└── pyproject.toml            # Project configuration
🚀 Quick Start
1. Core API Service
Start the FastAPI service:
cd kallia/core
pip install -r requirements.txt
uvicorn kallia_core.main:app --reload
The API will be available at http://localhost:8000
API Endpoints
Process Documents
POST /documents
Request body:
{
  "url": "path/to/document.pdf",
  "page_number": 1,
  "temperature": 0.7,
  "max_tokens": 4000
}
Create Memories
POST /memories
Request body:
{
  "messages": [
    { "role": "user", "content": "Hello" },
    { "role": "assistant", "content": "Hi there!" }
  ],
  "temperature": 0.7,
  "max_tokens": 4000
}
2. Interactive Playground
Start the Chainlit chat interface:
cd kallia/playground
pip install -r requirements.txt
chainlit run kallia_playground/main.py
The playground will be available at http://localhost:8000
3. Docker Deployment
Core Service
cd kallia/core
docker-compose up -d
Playground
cd kallia/playground
docker-compose up -d
💡 Usage Examples
Python API
from kallia_core.documents import Documents
from kallia_core.chunker import Chunker
from kallia_core.memories import Memories

# Convert document to markdown
markdown_content = Documents.to_markdown(
    source="document.pdf",
    page_number=1,
    temperature=0.7,
    max_tokens=4000
)

# Create semantic chunks
chunks = Chunker.create(
    text=markdown_content,
    temperature=0.7,
    max_tokens=4000
)

# Generate memories from conversation
messages = [
    {"role": "user", "content": "What is this document about?"},
    {"role": "assistant", "content": "This document discusses..."}
]
memories = Memories.create(messages)
REST API
# Process a document
curl -X POST "http://localhost:8000/documents" \
  -H "Content-Type: application/json" \
  -d '{
    "url": "https://raw.githubusercontent.com/kallia-project/kallia/refs/tags/v0.1.5/assets/pdf/01.pdf",
    "page_number": 1,
    "temperature": 0.7,
    "max_tokens": 4000
  }'

# Create memories
curl -X POST "http://localhost:8000/memories" \
  -H "Content-Type: application/json" \
  -d '{
    "messages": [
      {"role": "user", "content": "Hello"},
      {"role": "assistant", "content": "Hi there!"}
    ],
    "temperature": 0.7,
    "max_tokens": 4000
  }'
📊 Benchmark Results
Kallia has been extensively benchmarked against other popular document processing libraries using a comprehensive RAG (Retrieval-Augmented Generation) evaluation framework. The benchmark evaluates the quality of document chunking and retrieval performance across 100 test questions.
Performance Comparison
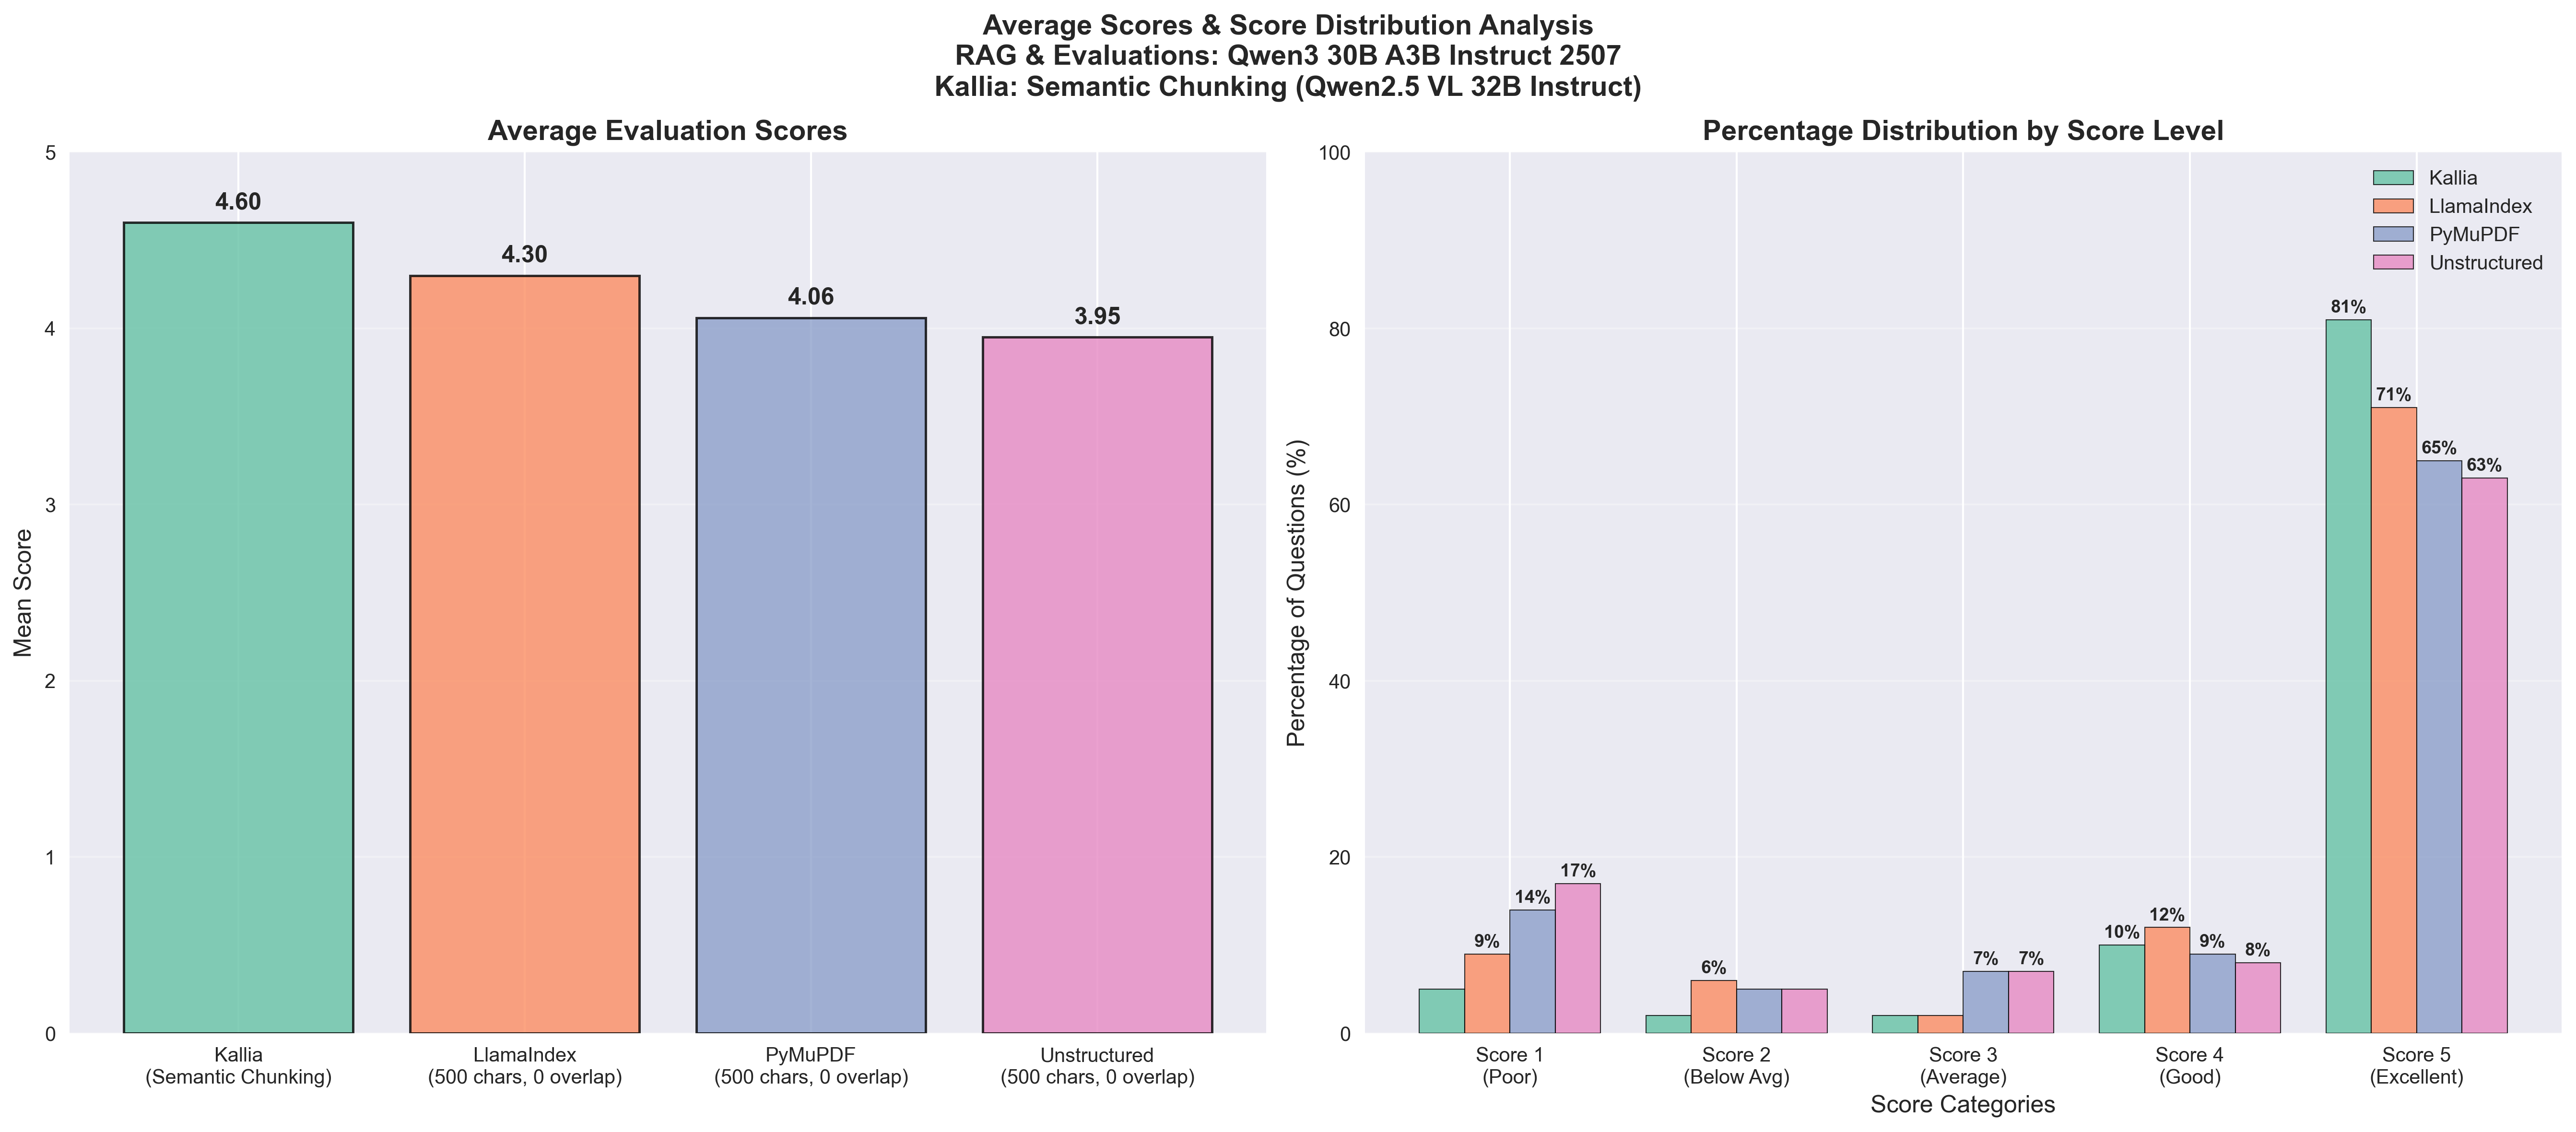
| System | Mean Score | Perfect Score Rate | Ranking |
|---|---|---|---|
| Kallia | 4.600 | 81.0% | 🥇 1st |
| LlamaIndex | 4.300 | 71.0% | 🥈 2nd |
| PyMuPDF | 4.060 | 65.0% | 🥉 3rd |
| Unstructured | 3.950 | 63.0% | 4th |
Key Advantages
- Highest Accuracy: Kallia achieves the highest mean score of 4.6/5.0
- Superior Perfect Score Rate: 81% of questions received perfect scores vs. 71% for the next best
- Semantic Chunking: Uses intelligent semantic chunking vs. fixed 500-character chunks with 0 overlap used by competitors
Benchmark Details
- Evaluation Model: Qwen3 30B A3B Instruct 2507
- Test Questions: 100 comprehensive questions across various document types
- Scoring: 1-5 scale (1=Poor, 2=Below Average, 3=Average, 4=Good, 5=Excellent)
- Chunking Method: Kallia uses semantic chunking with Qwen2.5 VL 32B Instruct
- Competitor Methods: Fixed 500-character chunks with 0 overlap
The benchmark results demonstrate Kallia's superior performance in document processing and retrieval tasks, making it the optimal choice for applications requiring high-quality document understanding and semantic chunking.
For detailed benchmark results and visualizations, see the benchmark/ directory.
🧪 Testing
Run the test suite:
python -m pytest tests/
Available tests:
test_pdf_to_markdown.py- Document conversion teststest_markdown_to_chunks.py- Chunking functionality teststest_histories_to_memories.py- Memory creation tests
🔧 Configuration
Environment Variables
Create a .env file based on the provided .env.example template in each directory:
Core Service:
cd kallia/core
cp .env.example .env
# Edit .env with your configuration
Playground:
cd kallia/playground
cp .env.example .env
# Edit .env with your configuration
Supported File Formats
Currently supported:
- PDF documents
The architecture is designed to be extensible for additional formats.
📝 License
This project is licensed under the Apache License 2.0 - see the LICENSE file for details.
🔗 Links
- Homepage: https://github.com/kallia-project/kallia
- Docker Hub: https://hub.docker.com/r/overheatsystem/kallia
- Issues: https://github.com/kallia-project/kallia/issues
- Documentation: https://kallia.gitbook.io/docs
👨💻 Author
CK - [email protected]
🏷️ Keywords
- document-processing
- semantic-chunking
- document-analysis
- text-processing
- machine-learning
- fastapi
- chainlit
- pdf-processing
- nlp
- ai
Built with ❤️ for intelligent document processing
Tag summary
Content type
Image
Digest
sha256:cedca7b3f…
Size
4 GB
Last updated
12 months ago
docker pull overheatsystem/kallia:0.1.6