rsundqvist/time-split
Companion app for https://github.com/rsundqvist/time-split
2.7K
rsundqvist/time-split repository overview
Time Split
Time-based k-fold validation splits for heterogeneous data.


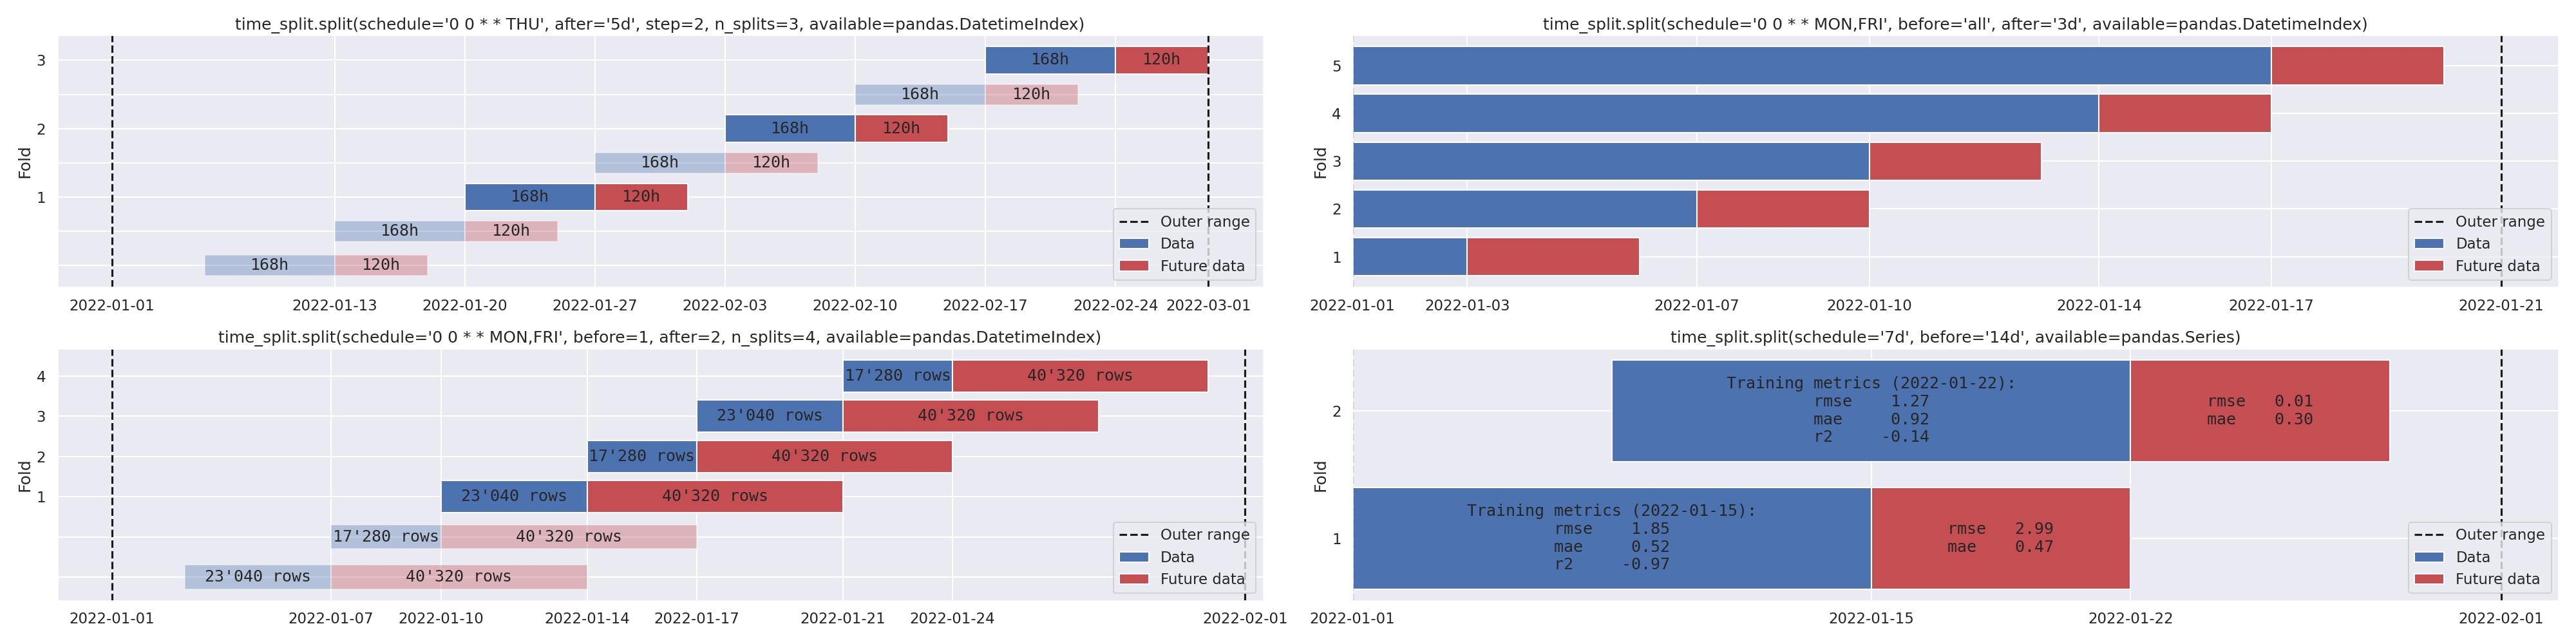
Folds plotted on a two-by-two grid. See the examples page for more.
About this image
The Time Split application (available here) is designed to help evaluate the effects of different parameters. To start it locally, run
docker run -p 8501:8501 rsundqvist/time-split
or
pip install time-split[app]
python -m time_split app start
in the terminal. You may use create_explorer_link() to build application URLs with preselected splitting parameters.
Documentation
Click here for documentation of the most important types, functions and classes used by the application.
Custom dataset loaders
Dataset loaders are a flexible way to load or create datasets that requires user input. The existing images (>=0.7.0)
can be extended to use custom loaders:
FROM python:3.13

RUN pip install --no-cache --compile time-split[app]
RUN pip install --no-cache --compile your-dependencies

ENV DATASET_LOADER=custom_dataset_loader:CustomDatasetLoader
COPY custom_dataset_loader.py .

# Entrypoint etc.
Loaders must implement the DataLoaderWidget interface. You may use
python -m time_split app new
to create a template project to get you started.
Custom datasets
To bundle datasets, specify a configuration file (e.g. DATASETS_CONFIG_PATH='s3://my-bucket/data/datasets.toml')
with the following keys:
| Key | Type | Required | Description |
|---|---|---|---|
label | string | Name shown in the UI. Defaults to section header (i.e. "my-dataset" below). | |
path | string | Required | First argument to the pandas read function. |
index | string | Required | Datetime-like column. Will be converted using pandas.to_datetime(). |
aggregations | dict[str, str] | Determines function to use in the 📈 Aggregations per fold tab. | |
description | string | Markdown. The first line will be used as the summary in the UI. | |
read_function_kwargs | dict[str, Any] | Keyword arguments for the pandas read function used. |
ℹ️ The read function is chosen automatically based on the path.
ℹ️ Additional dependencies are required for remote filesystems. You may use
EXTRA_PIP_PACKAGES=s3fsto install dependencies for the S3 paths used below.
See the DatasetConfig class for internal representation.
[my-dataset]
label = "IMDB Titles"
path = "s3://my-bucket/data/title_basics.csv"
index = "from"
aggregations = { runtimeMinutes = "min", isAdult = "mean" }
description = """This is the summary.

Simplified version of the
[Title basics](https://developer.imdb.com/non-commercial-datasets/#titlebasicstsvgz) IMDB
dataset. The description supports Markdown syntax.

Last updated: `2019-05-11T20:30:00+00:00'
"""
[my-dataset.read_function_kwargs]
# Valid options depend on the read function used (pandas.read_csv, in this case).
Multiple datasets may be configured in their own top-level sections. Labels must be unique.
Updating datasets
Datasets may be updated while the app is running. This is best done by changing the datasets config TOML file (e.g. by) writing a timestamp, as above.
Default timings:
- The dataframes returned by the dataset loader are cached for
config.DATASET_CACHE_TTLseconds (default = 12 hours). - The dataset configuration file is read every
config.DATASET_CONFIG_CACHE_TTLseconds (default = 30 seconds).
All datasets are reloaded immediately if the DATASETS_CONFIG_PATH file content hash changes.
Environment variables
See config.py for configurable values.
User choice
Users may lower some configured values by using the Performance tweaker widget in the ❔ About tab of application. To
set a lower default, add a DEFAULT_-prefix to the regular name.
PLOT_AGGREGATIONS_PER_FOLD=true
DEFAULT_PLOT_AGGREGATIONS_PER_FOLD=false
This will disable the (expensive) per-column fold aggregation figures, but users who need them can turn them back on.
Tag summary
Content type
Image
Digest
sha256:842d4d0a4…
Size
160.3 MB
Last updated
10 months ago
docker pull rsundqvist/time-split