snapotter/snapotter
Open-source, self-hosted file-processing infrastructure. 200+ tools, air-gap ready.
500K+
snapotter/snapotter repository overview
SnapOtter
Open-source, self-hosted file-processing infrastructure. Convert, compress, OCR, transcribe, and run local AI across image, video, audio, PDF, and documents, via UI, REST API, and pipelines. 200+ tools in one stack, on your own hardware. Your files never leave your network.


SnapOtter 2.2 is out. The
latesttag points at2.2.0: 200+ tools across image, video, audio, PDF, and files, plus a layer-based editor and local AI. See the release notes.
What is SnapOtter?
SnapOtter is a privacy-first alternative to cloud file-processing services. Convert, compress, edit, and transform files in your browser while the work happens on a server you control. No uploads to third parties, no per-file pricing, no SaaS lock-in. It runs as a single container (embedded PostgreSQL 17 and Redis 8) or as a small Docker Compose stack for production, and works on AMD64 and ARM64.
Quick start
One command, no setup. The container starts an embedded PostgreSQL 17 and Redis 8 on the loopback interface and keeps all data in the SnapOtter-data volume:
docker run -d --name SnapOtter -p 1349:1349 -v SnapOtter-data:/data snapotter/snapotter:latest
The same image is also published to GHCR as ghcr.io/snapotter-hq/snapotter:latest. Embedded mode turns off automatically as soon as you set DATABASE_URL, so moving to the Compose stack later is just a config change.
Open http://localhost:1349 and log in.
| Field | Value |
|---|---|
| Username | admin |
| Password | admin |
You will be asked to change your password on first login.
Production: Docker Compose
For production, run PostgreSQL and Redis in their own containers. Save this as compose.yaml:
services:
  snapotter:
    image: snapotter/snapotter:latest
    ports: ["1349:1349"]
    environment:
      DATABASE_URL: postgres://snapotter:snapotter@postgres:5432/snapotter
      REDIS_URL: redis://redis:6379
    volumes:
      - SnapOtter-data:/data
    depends_on: [postgres, redis]
    restart: unless-stopped
  postgres:
    image: postgres:17-alpine
    environment:
      POSTGRES_USER: snapotter
      # Change this for any non-local deployment.
      POSTGRES_PASSWORD: snapotter
      POSTGRES_DB: snapotter
    volumes: ["SnapOtter-pgdata:/var/lib/postgresql/data"]
    restart: unless-stopped
  redis:
    image: redis:8-alpine
    volumes: ["SnapOtter-redisdata:/data"]
    restart: unless-stopped
volumes:
  SnapOtter-data:
  SnapOtter-pgdata:
  SnapOtter-redisdata:
Then start the stack:
docker compose up -d
The first boot seeds an admin account from DEFAULT_USERNAME and DEFAULT_PASSWORD, both admin unless you set them. Set DEFAULT_PASSWORD on the snapotter service before the first start of any non-local deployment.
Supported tags and platforms
| Tag | Description |
|---|---|
latest | Latest release |
2.2.0 | Exact version |
2.2 | Latest patch in the 2.2.x line |
2 | Latest minor in the 2.x line |
| Architecture | GPU support | Notes |
|---|---|---|
linux/amd64 | NVIDIA CUDA | Full CUDA acceleration for AI tools |
linux/arm64 | CPU only | Raspberry Pi 4/5, Apple Silicon via Docker Desktop |
The same image runs on CPU or NVIDIA CUDA. Intel/AMD iGPU acceleration through VA-API, Quick Sync, or OpenCL is not supported for AI inference today; those systems run AI tools on CPU. See Docker Tags for benchmarks and version-pinning details.
Features
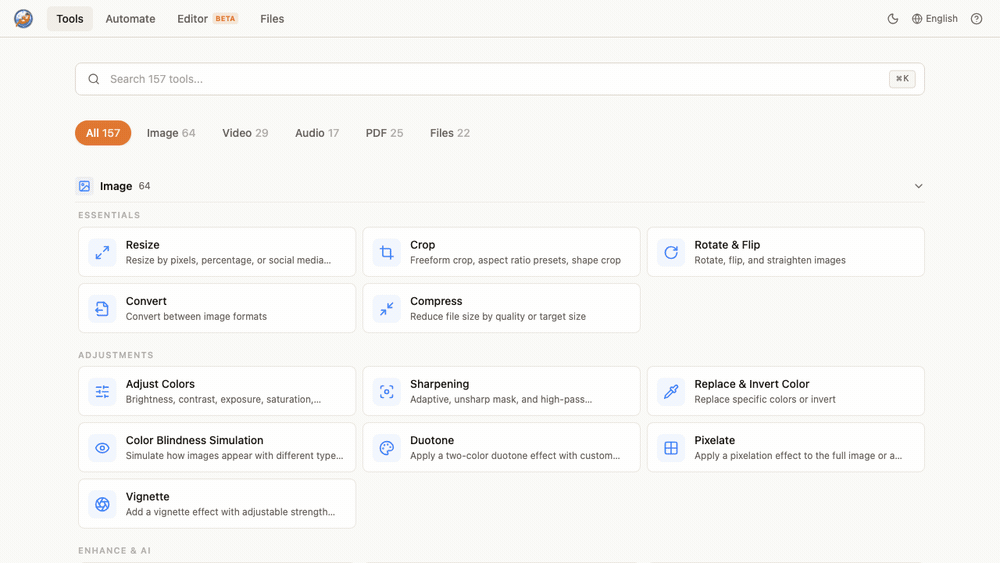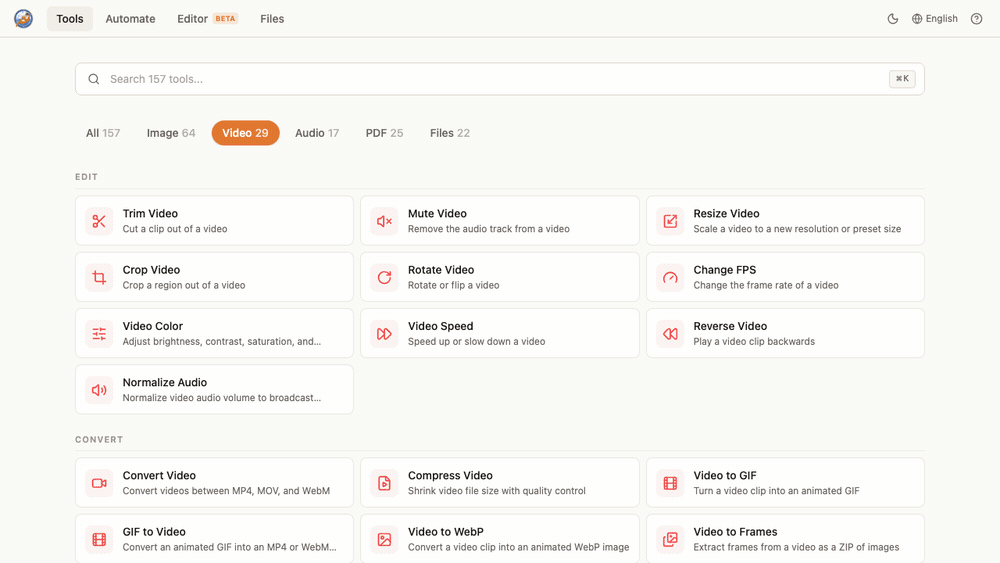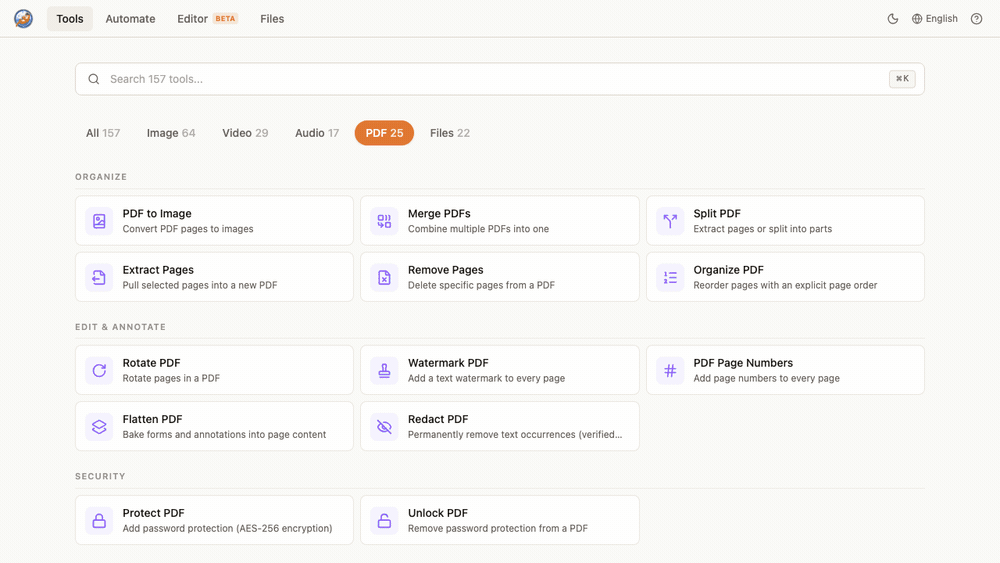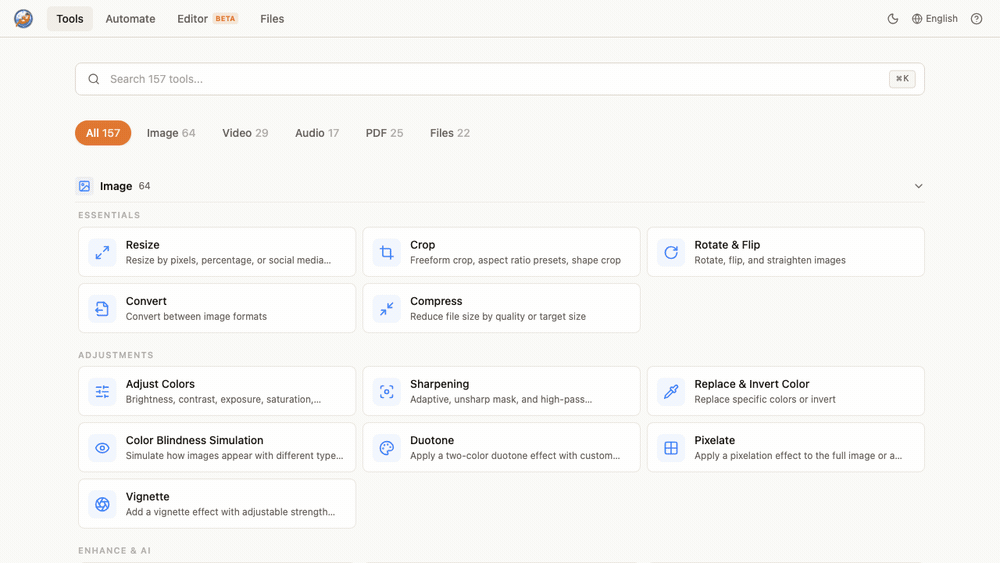
- 200+ tools across 5 modalities
- Image (107): resize, crop, compress, convert, watermark, color adjust, beautify screenshots, generate memes, vectorize, GIF tools, find duplicates, passport photos, and more. Supports 55+ input formats (including 23 camera RAW formats) and 17 output formats.
- Video (57): convert, compress, trim, resize, crop, merge, video-to-GIF, extract audio, stabilize, change FPS, burn or extract subtitles, and more.
- Audio (27): convert, trim, normalize, volume, fade, pitch shift, silence removal, noise reduction, merge or split, waveform, and more.
- Documents / PDF (29): merge, split, compress, convert (Word, Excel, PowerPoint, EPUB), protect or unlock, redact, watermark, page numbers, OCR, and more.
- Files (23): CSV, JSON, XML, and YAML conversion, CSV merge or split, chart maker, ZIP create or extract.
- Image editor: layer-based editor with brushes, shapes, adjustments, filters, curves, and keyboard shortcuts. Runs in your browser, processes on your hardware.
- Local AI: remove backgrounds, upscale images, restore and colorize old photos, erase objects, blur faces, enhance faces, extract text (OCR from images and PDFs), transcribe audio, auto-generate video subtitles, expand canvas, and fix transparency. All on your hardware, no internet required. Built-in Fast OCR adds about 25 MiB to the official image; the optional accuracy pack installs on demand.
- OIDC / SSO: log in with Google, GitHub, Okta, or any OpenID Connect provider.
- 21 languages: including Arabic (with RTL support), Chinese (Simplified and Traditional), French, German, Hindi, Japanese, Korean, Portuguese, Russian, Spanish, and more.
- Pipelines: chain tools into reusable workflows, 20 steps by default (
MAX_PIPELINE_STEPS). Import and export as JSON. Batch size is unlimited in this image (MAX_BATCH_SIZE=0). - REST API: every tool available via API with API key auth. Interactive docs at
/api/docs. - Privacy first: your files never leave your network. Anonymous product analytics (which tools are used and which errors happen, never file data) are on by default. An admin can turn them off instance-wide in Settings, or set
ANALYTICS_ENABLED=falseto disable them completely.
Configuration
Common environment variables (set on the snapotter service). Use 0 for unlimited or auto where noted.
| Variable | Default | Description |
|---|---|---|
DATABASE_URL | (unset) | PostgreSQL connection string, and the connection every request is served on. Required for the Compose stack. Leave it and REDIS_URL unset and the container runs its own PostgreSQL and Redis. |
DATABASE_MIGRATION_URL | (unset) | Available from 2.3.0. Privileged connection for migrations and grants, opened at boot and closed before the first request. Set it and DATABASE_URL becomes a role that can only read and write rows. Leave it unset to run single-role, which is what the example above does. The 2.2.0 image ignores it and needs DATABASE_URL to name the database owner. |
REDIS_URL | (unset) | Redis connection string. Same rule as DATABASE_URL. |
AUTH_ENABLED | true | Set false to run without login (creates a synthetic anonymous admin). |
DEFAULT_USERNAME | admin | Initial admin username. |
DEFAULT_PASSWORD | admin | Initial admin password. Change this for any non-local deployment. |
MAX_UPLOAD_SIZE_MB | 0 | Max upload size in MB. 0 is unlimited. |
MAX_BATCH_SIZE | 0 | Max files per batch. 0 is unlimited. |
CONCURRENT_JOBS | 0 | Worker concurrency. 0 auto-detects from CPU. |
PROCESSING_TIMEOUT_S | 0 | Per-job timeout in seconds. 0 is unlimited. |
RATE_LIMIT_PER_MIN | 1000 | API requests per minute per client. 0 disables the limit. |
SESSION_DURATION_HOURS | 168 | Login session length in hours. |
TRUST_PROXY | loopback,linklocal,uniquelocal | Which peers may set the client IP via X-Forwarded-For. Private-network peers only by default, so a reverse proxy on a Docker network or a LAN is believed and a public client's forged header is not. Set true only if a proxy you control sits in front on a public address. |
ANALYTICS_ENABLED | true | Set false to disable anonymous product analytics entirely. |
EXTERNAL_URL | Public URL of the instance, required for OIDC redirects. | |
SQLITE_MIGRATE_PATH | Path to a 1.x SQLite database to import on first boot. |
OIDC, SSO, S3 storage, and the full variable reference are documented in Configuration and OIDC / SSO.
Volumes
| Path | Purpose |
|---|---|
/data | AI models and persistent user files; in single-container mode also the embedded PostgreSQL and Redis data. Back this up. |
/tmp/workspace | Temporary processing files (auto-cleaned). |
In the Compose stack, PostgreSQL and Redis keep their own volumes (SnapOtter-pgdata, SnapOtter-redisdata).
Ports
| Port | Purpose |
|---|---|
1349 | Web UI and REST API |
NVIDIA CUDA acceleration
The amd64 image bundles CUDA. With an NVIDIA GPU and the NVIDIA Container Toolkit installed, add this to the snapotter service to accelerate background removal, upscaling, and transcription. OCR remains CPU-based and works unchanged on the same host:
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: 1
              capabilities: [gpu]
The image auto-detects NVIDIA CUDA at runtime and falls back to CPU when CUDA is unavailable. Mapping /dev/dri for Intel or AMD GPUs does not accelerate SnapOtter AI tools today. Benchmarks are in Docker Tags.
Upgrading from SnapOtter 1.x
v1.x stored data in SQLite. Back up the whole /data volume before you start, not just snapotter.db: 1.x runs SQLite in WAL mode, so most of your recent data is sitting in snapotter.db-wal. Then set SQLITE_MIGRATE_PATH=/data/snapotter.db on the snapotter service for the first boot and remove the variable once the migration succeeds. Your files and settings are preserved. Full walkthrough: Upgrading from 1.x.
Documentation
- Getting Started
- Configuration
- Deployment
- Docker Tags and GPU
- OIDC / SSO
- REST API
- Source on GitHub
- Report an issue
License
Dual-licensed under AGPLv3 and a commercial license. Use, modify, and self-host freely under the AGPLv3; if you run a modified version as a network service, you must make your source available under the AGPLv3. For proprietary or SaaS use where source disclosure is not suitable, a commercial license is available. Contact [email protected].
Tag summary
Content type
Image
Digest
sha256:2e11b4fa9…
Size
1.7 GB
Last updated
about 2 months ago
docker pull snapotter/snapotter